ray @raydistributed
A distributed compute framework for scaling AI workloads. Created and developed by @anyscalecompute. docs.ray.io Joined August 2019-
Tweets2K
-
Followers12K
-
Following2
-
Likes2K
Kubernetes doesn’t know what a Ray cluster is. So teams keep hand writing the same Deployments, Services, and recovery scripts to run Ray on it. KubeRay fixes that: autoscaling, fault tolerance, and zero downtime upgrades for Ray, built into Kubernetes. na2.hubs.ly/H08qhRS0

@Xoople processes 500,000 km² of satellite imagery in under 5 minutes on 12 A10 GPUs with Anyscale on @Azure. A single request can fan out to 2 trillion pixels. 15 engineers without a dedicated infra team. Read the case study: na2.hubs.ly/H08qgTD0.
Run Reflection's Beam at scale in your own account for full sovereignty but without managing infra with Ray Serve LLM on Anyscale!

Excited to announce Day 0 support for Reflection's Beam model on Ray Serve LLM! Beam is Reflection's first open-weight model, advancing the frontier of Western AI in the 500B-parameter class. Built as a sparse MoE model, Beam is optimized for coding, agentic workloads, and
Heading to @PyTorch Conference next week? ☕ Come hang at the Coffee Club with the teams behind Ray and vLLM, two key projects under the PyTorch Foundation. Hosted by Anyscale, @inferact and @nscale. Request your spot here: na2.hubs.ly/H08rrdP0
Open Source AI Week kicks off tomorrow 🎉 📍 The Midway, SF, 6pm 👇 na2.hubs.ly/H08nMYB0 Join us alongside other key players in AI helping organizations adopt and scale their use of open-source.

We post-train GLM-5.3 Flash in a sandbox that reproduces the Bits Investigation tools over archived scenario data. Our async RL stack is based on #SkyRL, with efficiency and reliability enhancements in our internal fork. Training and inference run concurrently, with a staleness budget for off-policy updates.
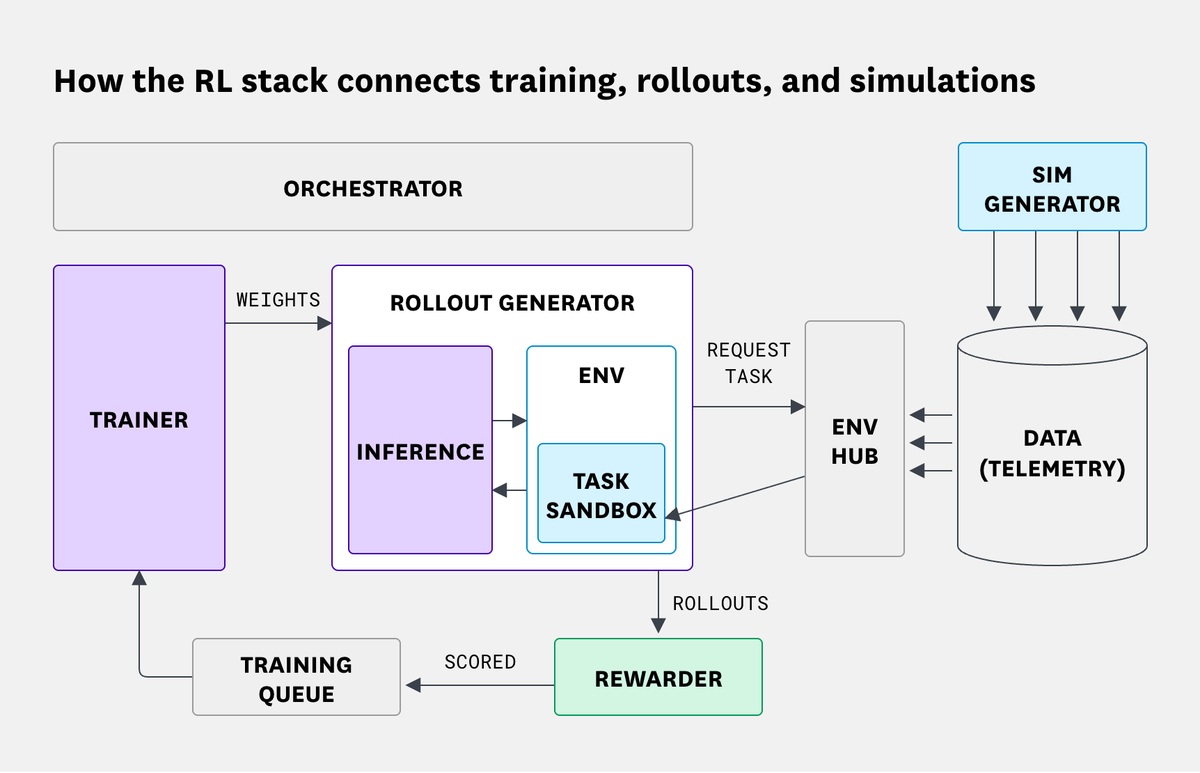

datadog ai research used SkyRL to post-train GLM 5.3 Flash to perform at the pareto frontier for their SRE eval @bthecohen and team were some of the earliest users of SkyRL at scale, really cool to see these results finally out! great tech report as well
Meet Scout 1.0, our first AI model built for investigating production incidents. Scout matches frontier-model investigation quality at a fraction of the cost, which makes it practical to investigate more issues, earlier. We trained Scout on realistic simulations built from
Great to see this out! Datadog's new SOTA model for investigating production incidents. Their in-house training stack builds on top of SkyRL! 🚀🚀🚀
Meet Scout 1.0, our first AI model built for investigating production incidents. Scout matches frontier-model investigation quality at a fraction of the cost, which makes it practical to investigate more issues, earlier. We trained Scout on realistic simulations built from

Datadog post-trained GLM-5.3 Flash via RL on real-incident sims. Matches frontier SRE performance at much lower cost. Their RL stack is built on top of SkyRL! Check out the technical report web-assets.dd-static.net/42588/17920710…
Meet Scout 1.0, our first AI model built for investigating production incidents. Scout matches frontier-model investigation quality at a fraction of the cost, which makes it practical to investigate more issues, earlier. We trained Scout on realistic simulations built from
@ChefRobotics trains the Vision-Language-Action models behind its food assembly robots 10x faster on Anyscale, with 92% scaling efficiency across multi GPU runs on 16 A100s. Read the story: na2.hubs.ly/H08q5bh0

@coinbase is building an agent-first ML platform where AI agents watch model performance and trigger retraining on their own. Aman Choudhary on how Ray on Anyscale helps them run up to 1 billion inferences a day na2.hubs.ly/H08nMPc0
We’re joining Open Together with @huggingface and friends this Friday to support everyone building AI with open-source SF, Oct 16, 6pm 👇 na2.hubs.ly/H08m4Mv0
Our upcoming webinar will cover how to design scalable distributed inference systems for production AI applications, from classic ML models to large language models. Learn how Ray Serve delivers high-throughput, low-latency serving, and how to evaluate the performance tradeoffs in autoscaling, batching, routing, and inference-engine optimization. Topics include: - Building Ray Serve applications with deployments, composition, and load-aware request routing - Deploying and scaling LLM endpoints with Ray Serve LLM on engines like @vllm_project and @sgl_project - Optimizing the inference engine with the KV cache, paged attention, prefix caching, and continuous batching - Scaling frontier models with KV-cache-aware routing, prefill/decode disaggregation, and wide expert parallelism for mixture-of-experts (MoE) models - Deploying Custom LLMs on Anyscale and Integrating Them with Agentic Platforms (Claude Code, Cursor, Codex) - Comparing costs across self-hosted GPUs, subscriptions, and token-based API billing. Register: na2.hubs.ly/H08hfbl0

We’re heading to Long Horizon by Encord next week! 📍Come meet our team at booth P1 and hear from our team: 🎤 From Petabytes to Policies: Scaling the Physical AI Data Engine with Ray 🎤 Why Sim Platforms Shouldn’t Be a Batch Job: Scaling Synthetic Data Generation with Ray na2.hubs.ly/H08jzKS0

Anyscale is heading to PyTorch Conference North America, October 20 and 21 in San Jose. Catch our sessions on SkyRL and Ray Core, drop by our Meet the Developers session on DeepSpeed and Ray with the Anyscale team, swing by booth P9, and come recharge with us at the Coffee Club lounge just off the venue. na2.hubs.ly/H08nkrd0


People who are really serious about applied AI should train their own models. Sharing our “Owning Intelligence” series on how we built, evaluated, and post-trained a fraud agent at Coinbase—from using frontier models to owning a model optimized for our task. Part 1 — Build lnkd.in/grtg_gfF Part 2 — Evaluate lnkd.in/g-6DKdZ8 Part 3 — Own lnkd.in/g9ET_4at @akshit_trehan @anyscalecompute, @erictang000 , @sumanthrh , @seiji_________ ,
@Xoople is building toward petabyte-scale processing of satellite imagery of the whole planet. VP of Engineering Milos Colic on why the team runs Ray on Anyscale instead of building its own AI compute layer. na2.hubs.ly/H08gWwX0
After a year of close collaboration with the Azure team, we're excited to announce the general availability of Anyscale on Azure! Anyscale on Azure is managed Ray on AKS, for the whole loop from data processing to training to inference. Some highlights: - Deploys on AKS in your own Azure subscription - Data and models stay in your subscription - A first-class resource in the Azure portal - Sign in with Microsoft Entra ID - Billed through your Azure invoice, counting toward your existing Azure consumption commitment This is the product of a very deep collaboration with the AKS team and is just the start of what we'll be shipping on Azure. Learn more: anyscale.com/product/azure
New: Anyscale on @Azure, now in GA. Anyscale on Azure is generally available. Run the full AI loop on AKS in your own subscription. Own your AI on open source Ray, keep data and models in your tenant, and get more work from every GPU. Deploy from the Azure portal and pay through
New: Anyscale on @Azure, now in GA. Anyscale on Azure is generally available. Run the full AI loop on AKS in your own subscription. Own your AI on open source Ray, keep data and models in your tenant, and get more work from every GPU. Deploy from the Azure portal and pay through your Azure bill. na2.hubs.ly/H08dWKQ0

PyTorch @PyTorch
518K Followers 104 Following Tensors and neural networks in Python with strong hardware acceleration. PyTorch is an open source project at the Linux Foundation. #PyTorchFoundation
Jim Fan @DrJimFan
600K Followers 3K Following NVIDIA Director of Robotics & Distinguished Scientist. Co-Lead of GEAR lab. Solving Physical AGI, one motor at a time. Stanford Ph.D. OpenAI's 1st intern.
Erik Bernhardsson @bernhardsson
60K Followers 4K Following Building everyone's favorite AI infrastructure platform @modal
Hugging Face @huggingface
823K Followers 227 Following The AI community building the future. https://t.co/TpiXQMQ9rZ
Robert Nishihara @robertnishihara
17K Followers 876 Following Co-founder @anyscalecompute. Co-creator of @raydistributed. Previously AI research at Berkeley.
merve @mervenoyann
93K Followers 5K Following (mer-veh) open-sourceress at @huggingface 🧙🏻♀️ DM me for any feedback about HF 🤗 https://t.co/MhrMkGTm7p
(((ل()(ل() 'yoav)))... @yoavgo
91K Followers 2K Following
Weights & Biases @wandb
49K Followers 1K Following Experiment tracking and hyperparameter sweeps for AI researchers and engineers, by @CoreWeave. Part of CoreWeave Forge.
Charles 🎉 Frye @charles_irl
20K Followers 3K Following memer of technical staff at @modal. he/him. ex @full_stack_dl, @weights_biases (acq. @CoreWeave), phd Berkeley @Redwood_Neuro.


Temple Compute @templecompute
5 Followers 90 Following Draw a pipeline or write it in Python. Reduce time & cost for computational scientists.
Lucho Juárez @luchoojuarez
176 Followers 885 Following The greatest rewards come from doing the things you fear the most

crumbsofcookies @crumbsofco13678
0 Followers 102 Following
Zeleke A. @ZelekeA
134 Followers 2K Following
Ibnul Jaif Farabi @IbnulJaifFarabi
90 Followers 1K Following I'm an Electrical and Computer Engineer, Author, Teacher, Photographer, Cook, Baker, Dress Maker, Artist, Pianist, Gardener, Multilingual from New York City.
Hayden Ayres @hayden_ayr81393
11 Followers 130 Following
Jay Yun @Jayyun98_dev
70 Followers 593 Following AI Engineer (6y) LLM services (15M user) / LLMops platform. Sharing thoughts and experiences
brent smith @brent_rc
271 Followers 415 Following NQ Cowboys fan. Brento on Draftstars. NRL, PGA and NFL player. $TAO holder….. for a long time. 3 kids, everything for them
sree_m @Jsmuppalla
1 Followers 91 Following
Codex @Prayer3th
0 Followers 44 Following
Aditya Ray @Aditya_Ray_03
14 Followers 169 Following Recent AI & Data Science grad. Building an LLM inference engine from scratch. Open to ML engineer / LLM inference roles.

Sub Zoro @sub_zoro
5 Followers 1K Following
Andrew Wenger @andrewwenger
6K Followers 3K Following
RKP @RKP_1966
138 Followers 2K Following
Mostafa Albana @mostafa_albana_
553 Followers 5K Following Senior Software Engineer / Architect / Web #Java #Quarkus #Spring framework #Python #Javascript #Node.js #Angular Interested in machine learning and statistics.
Chandra Shekhar @cj82456617
0 Followers 43 Following
Harsh Gadodia @haxgad
79 Followers 303 Following I’m a software engineer. I like code, music, coffee, and writing.
king @bmwforever23
17 Followers 1K Following
jeremyhampers @jeremyhampers
0 Followers 195 Following
Brent Stewart @VMachinesAI
11 Followers 458 Following Co-founder & Chief Scientist, Virtuous Machines. Morally & epistemically robust AI. MA, Philosophy (@SFU); PhD, Psychology (@UBC).
Sheek OGP @SheekOGP
20 Followers 213 Following

Gilles Legoux (glegou... @gilleslegoux
20 Followers 115 Following Software Engineer 💻 @Criteo ✨Tweets about Tech in EN/FR
Aaron Law @aaronlaw
79 Followers 3K Following
NITRO2 Diseño web @nitro2ar
1K Followers 6K Following CREAMOS TU ESPACIO! Utilizamos las últimas tecnologías para ofrecerte el diseño y la programación de un espacio web funcional, atractivo y autogestion.
Halen Hell @halen_hell
0 Followers 1K Following
weily @weily38308560
4 Followers 494 Following
Guido @FettGuido
1 Followers 314 Following

Pat @PattConley
0 Followers 48 Following
Jyotin Goel @GoelJyotin94856
131 Followers 1K Following Research @domynai | https://t.co/aJ8hRxzHSE | random(qkT) (Opinions are mine, doesn’t reflect my employer)

Mani @mbs_1231
46 Followers 308 Following Conscious | Anhad - अनहद | Teaching models to do what I can & more...... ML Engineer @ https://t.co/oNhMRqfkt6

bmbharath @barathhbm
419 Followers 5K Following 💻 Software Engineer | 📈 Trading,Investing |Geopolitics 🌎|Technology 💻|


Mohammed Junaid Ahmed @MdJunaidah16
42 Followers 184 Following AI Engineer | MTech at BITS-Pilani | https://t.co/sHdtEb5yaA | https://t.co/ywXe8Q2cqk
Viswa Ravichandran @viswa_ravi_
78 Followers 2K Following Love to paint pixels on the screen. #HPC #GPUProgramming #ComputerVision #Rendering #AI
Tech @Tech_Minddd
0 Followers 20 Following
Akshit Vakati Venkata @akshitvv13921
4 Followers 16 Following
Rishwanth Thottempudi @Rishwanth2594
4 Followers 322 Following

Alex Ren @AlexFellowsFund
810 Followers 4K Following Founding Partner at Fellows Fund, a Silicon Valley based AI fund. Investor in Generalist, Gamma, Higgsfield, Corgi, Replit, Abridge, Harmonic, etc.
Darren NYC @BrainPundit
7 Followers 2K Following
Ray Summit @Ray_Summit_Live
937 Followers 3 Following Join us the #Ray community in SF for keynotes, #Ray deep dives, #llm sessions and lightning talks exploring the future of machine learning and scalable #AI.
Anyscale @anyscalecompute
14K Followers 4 Following The best way to run @raydistributed, the distributed compute framework for scaling AI workloads.Trends for United States
You might like