

AfterQuery @AfterQuery
Applied research lab curating data solutions to accelerate foundation model development. afterquery.com Joined February 2025-
Tweets88
-
Followers4K
-
Following9
-
Likes194
@AfterQuery is partnering with @nvidia to help enterprises post-train Nemotron 3.5 Super VL. The future of enterprise agents is open. 💚

Big shoutout to all of our partners for making Nemotron 3.5 Super VL their own through post-training 🙌 Here’s what they’ve built 🧵
@NVIDIAAI @hebbia Learn more: afterquery.com/blog/post-trai…
@AfterQuery just moved an open model past the cost-accuracy frontier in finance. We post-trained @NVIDIAAI Nemotron 3.5 Super VL on expert credit tasks with @hebbia. Perfect solved: 47% to 74%. That beats Sol 6, and lands within 3 points of Astra 6, at about 1/7 the cost. Link to the full case study in replies.
@AfterQuery’s throwing a sftw happy hour with @NVIDIAAI tonight at 6:30pm. reply for an invite.

Read more about our experiment using SkyRL here: afterquery.com/blog/improving… To learn more about our tasks and reward design, reach out to us at [email protected]
Not all coding data is created equal. Using only 500 tasks from @AfterQuery's SWE agent dataset, our internal post-training team was able to improve Qwen3.8-27B-Medium by 11.3 points in only 15 steps of GRPO. Read more about our training experiment in the blog post linked in the comments.
Working on AI research, post-training, or deployment? Come meet the @AfterQuery Team during SF Tech Week. Wed 10/7: Frontier of Finance with Goldman Sachs Fri 10/9: Rooftop happy hour We'd love to see you there. Details + RSVPs below.
@AfterQuery is hosting a panel with @GoldmanSachs during SF Tech Week to discuss the frontier of finance! RSVP in the replies👇
People still underestimate how large the data market will become. Better models do not reduce demand for data. They increase the number of useful things models can learn. The frontier keeps moving, so the data has to keep getting harder.
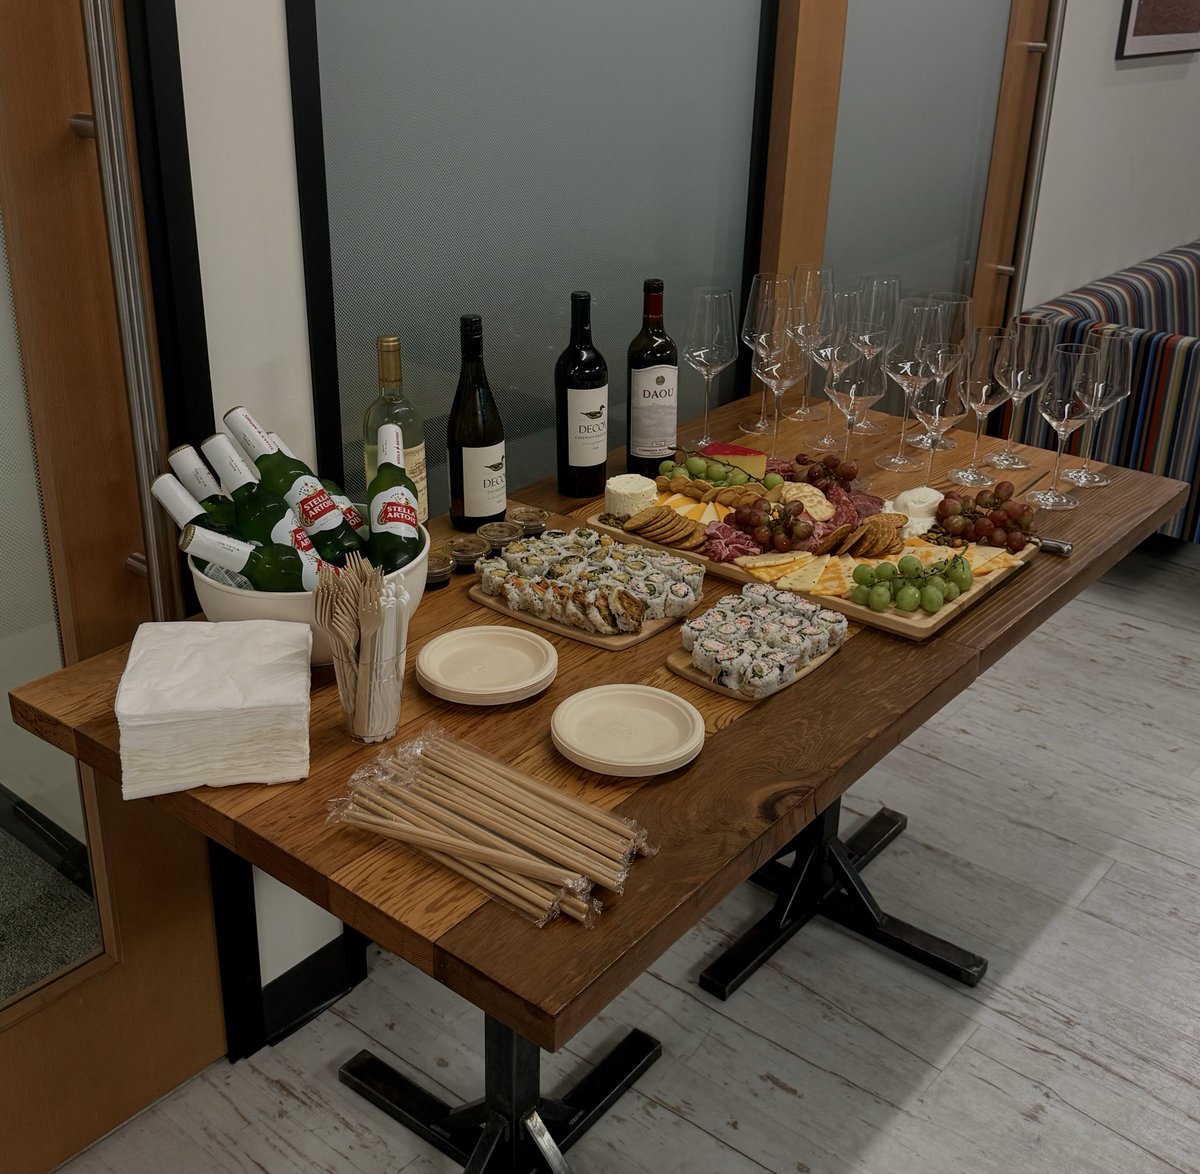
last nights spread for @AfterQuery‘s 3rd poker night now hosting these biweekly♠️
fluffy work trialers at the @AfterQuery office today


If you're free tomorrow night, @AfterQuery is hosting a researcher poker night tmr @ 8:30pm rsvp for deets👇
The @AfterQuery post-training team helped patch a critical LoRA weight-loading bug in SkyRL today. Check out our PR in the replies.

Gemini 3.8 set SOTA on DeepSWE at 9am. Muse Spark 1.3 took it back at 12:30pm. Incredible work from the MSL coding team.
Muse Spark 1.3 is rolling out today with frontier performance almost too cheap to meter. This is the biggest jump we've made so far on coding and agentic work. Try it in Muse Code and our API. Next up 🍉 and Muse Spark open weights releases coming soon.

Legal and finance are two of the highest-impact domains to crack. 3.8 Flash now leads both Harvey’s Legal Agent Benchmark and Vals Finance Agent v2. Huge congrats to GDM ⚡️
Introducing Gemini 3.8 Flash, another jump in Gemini's agentic + coding capabilities, and our 3rd updated Flash model in only 6 weeks... This model has been a ton of fun to work with, excited to see what you all think!


New @nvidia DGX Spark just came in. Hyped to put it to work and eliminate inference costs on a few of my workflows.

This is a historic moment for Korean sovereign AI and the open weights ecosystem writ large. We look forward to supporting Motif and the Korean AI ecosystem as they push the frontier of open intelligence. Motif 3 leads its comparison set on τ³-Banking, and posts 94.7 on τ²-Bench Telecom, 74.9 on Terminal-Bench 2.1, and 76.2 on SWE-bench Verified. It’s also great to see @nvidia's open foundation put to use here - Motif 3's post-training was done via NeMo-RL. In a world where it’s easy to assume that the AI race is already won, the team at Motif is proof that the field is open, and we’re still at the starting line.
Congratulations to the @motif_tech team on the release of Motif 3! AfterQuery is proud to have served as the sole data partner on this model.


Saad Bin Masud @SaadBinMasud_
0 Followers 166 Following
Frosty @padraigjudge_
53 Followers 288 Following

Ebrahim Songhori @esonghori2
285 Followers 1K Following Founding Technical Staff @RicursiveAI AlphaChip | AI for Chip Design | ex-@GoogleDeepMind, ex-Google Brain
Jonathan @heyjonmor
69 Followers 2K Following Founder | Engineer | Designer | Husband & Father | ex-microsoft ex-janitor

Daniel Moore @denmarkdreamin
1 Followers 158 Following Building physical AI that works in the real world. Investor and operator. Advisor to startups.

Jacob @jacobcorrales
22 Followers 97 Following
Jack Longarzo @JackLongarzo
3K Followers 3K Following

codykandarian @codycodess
23 Followers 493 Following Software Intern @SpaceX - opinions are my own Interested in applied ai, inference and product
Rosenburg @Vlad1mpales
246 Followers 5K Following


Justin E Samuels @ThugDebugger
11K Followers 5K Following @RenderATL & @AtlantaTechWeek Founder-CEO, Ex-Senior Engineer @mailchimp (@intuit),@msstate Alumnus 🐮🔔, 🇯🇲🇺🇸, ΦΒΣ|ΘΙ|SPR11|7. 🐈⬛ | @Inc 30 under 30

Joel @Joel96589312632
14 Followers 157 Following
Dylan Siegel @D1siegel
127 Followers 3K Following
Karen Zhou @karenzzhou
54 Followers 136 Following post training for coding usability @thinkymachines, ex Claude Code and coding behavior @anthropicai
Sonny @corleone_gmi
332 Followers 2K Following Full-Stack Dev | Previously @competesai | @miladycolombia enjoyoor.
satyam @satiyum
591 Followers 2K Following data for robotics and health unlock the future we need. founder, https://t.co/ji2txiGF8Q, https://t.co/7eH2e6LVXg, https://t.co/AciEw5Exhq
P “레이몽” K @khpark429
23 Followers 66 Following
Danilo Soto @DaniloJSoto
24 Followers 3K Following
cristiano @windywxf
84 Followers 6K Following
Rohith @Rohith_RK20
1 Followers 242 Following SRE & MLOps | Kubernetes • Cloud • CKA | Learning, building & breaking things 🚀
KONO @dia_an_rath
149 Followers 5K Following Whether We Live or Die that's for heavens to decide the one who gives in to their fear loses.
Nathan Stevenson @NathanStvnsn
318 Followers 2K Following Building worlds from enterprise data. Live gyms, traces, knowledge graphs. Founder, https://t.co/zbPOgzphjG. AI Fintech 100. Quant @CQS, IB @BNP Paribas.
Jeff Murray @jmurray10_
30 Followers 719 Following Building AI agents that know when not to act. Classical agent design + LLMs, evals, human-in-the-loop. Open source: agent_design_peas. Finance & ops automation.


Zams @Zams31407155
13 Followers 96 Following
Nick Wilkinson @mrnickwilkinson
8 Followers 202 Following Obsessive by nature. Contrarian by trade. Builder by choice. Future brand, growth systems, and the occasional big idea. 💎
sr71blr @sr71blr
943 Followers 7K Following


Dufflebag @dufflebagtrades
1 Followers 51 Following
dufflebag @dufflebag0121
2 Followers 16 Following

Herm @yexd17
132 Followers 3K Following

Morgan Bruce @morganjbruce
236 Followers 1K Following i like building things • prev @CausalyAI @mazedesignHQ @Onfido
Rishabh Gupta @Rishabh7696
8 Followers 573 Following
Varsh Sridharan @VarshineSri
1K Followers 2K Following Product @Microsoft AI | Reasoning agents, evals, RL. UIUC alum. "you can just do things" Nerding out on Robots, AI & Longevity Views & opinions my own.



Sam Jung @sammjung_
256 Followers 213 Following @afterquery. prev @ycombinator @allen_ai, @statedept
Carlos Georgescu @CarlosGeorgescu
663 Followers 1K Following @afterquery interested in AI research, quantitative finance & poker
You might like


















