-
Tweets232
-
Followers45K
-
Following1
-
Likes31
In Apache Spark 4.2, retrieval (NEAREST BY), governed semantics (metric views), and agent access (Spark Connect) run inside the engine, next to the data and under the same permissions, instead of in separate services. Download Spark 4.2 👉 spark.apache.org/downloads.html #ApacheSpark #AI #GenAI
Felix Cheung (Apache Spark PMC, @nvidia) and @lisancao on running Spark SQL and DataFrames on GPUs with NVIDIA’s cuDF plugin, no job rewrites. Snapchat’s A/B experimentation pipeline: 10 PB of new data a day, processed with Spark. On GPUs, 70-90% lower cost. Also Spark Connect, including how a Spark Connect Gateway can sit in front of multiple servers, GPU ones included. 🎥 Full talk: youtu.be/nL6NVivpIfQ #ApacheSpark #SparkConnect #cuDF
Spark SQL picks up several additions in Apache Spark 4.2, out now: SET PATH for object resolution, scripting cursors, QUALIFY for window results, SYSTEM.BUILTIN qualification, plus Theta sketches, time_bucket, and top-K max_by/min_by. More analytical work stays in SQL. 🔗 Download Spark 4.2: spark.apache.org/downloads.html #ApacheSpark #SparkSQL #SQL
Apache Spark 4.2 is out. Python Data Sources let you build batch or streaming readers and writers in Python, no JVM or Scala, used through the standard spark.read interface. Spark 4.2 adds time and memory profiling so they're easier to tune and operate. 🔗 Download: spark.apache.org/downloads.html #ApacheSpark #PySpark #Python
Auto CDC arrives in Spark Declarative Pipelines with Apache Spark 4.2: first-class SCD Type 1. Configure how change events update a target table, and Spark handles deletions and out-of-order events, in place of hand-written merge logic. 🔗 Download Spark 4.2: spark.apache.org/downloads.html #ApacheSpark #CDC #DataPipelines #ETL
.@ApacheAirflow is a popular orchestrator, but it often has little visibility when a Spark job fails. At Airflow Summit 2026, @lisancao sat down with Andreas Neumann to discuss Spark Declarative Pipelines. Spark owns the pipeline graph, derives dependencies, and handles session lifecycle and writes, while Airflow orchestrates Spark as an application. 🎥 Watch the full conversation: youtube.com/watch?v=dS5Awl… #ApacheSpark #ApacheAirflow #DataEngineering
Headed to #CommunityOverCode Glasgow? 🏴 Oct 11–14 features Apache Spark sessions on: 🔸 Resource auto-sizing 🔸 Spark 4.2 heterogeneous executors 🔸 CDC patterns 🔸 PySpark transpilation 🔸 Agent-native observability 🔗 See the schedule: communityovercode.apache.org/events/glasgow… #ApacheSpark
Grounding agents in trusted data is a theme in Apache Spark 4.2: NEAREST BY for retrieval, metric views for governed numbers, Spark Connect for access. Retrieval and metrics live next to the data, under the same permissions. 🔗 Download Spark 4.2: spark.apache.org/downloads.html #ApacheSpark #AIAgents #RAG #GenAI
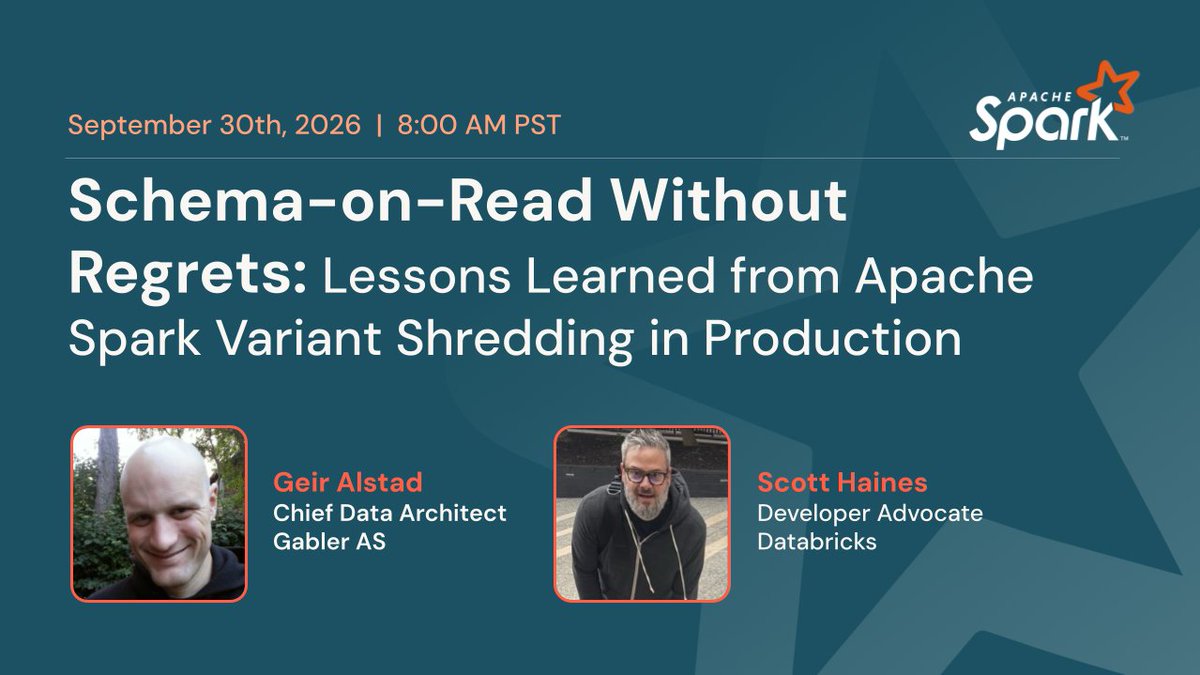
Schema-on-Read Without Regrets: Lessons Learned from Apache Spark Variant Shredding in Production x.com/i/broadcasts/1…
Arrow-optimized Python UDFs are on by default in Apache Spark 4.2: existing UDFs take the faster columnar path with no rewrite, dropping the row-by-row JVM/Python serialization cost. Plus Pandas 3 and zero-copy handoff to Polars and @duckdb. 🔗 Download Spark 4.2: spark.apache.org/downloads.html #ApacheSpark #PySpark #ApacheArrow #Python
Join us next Wednesday for Schema-on-Read Without Regrets! Geir Alstad (Gabler AS) and @newfront (@databricks) will walk through Spark Variant shredding in a real pipeline. 🗓️ Wed, Sept 30 · 8:00 AM PT 🎟️ Register: luma.com/open-z92a #ApacheSpark

Open Lakehouse + AI hits Bellevue in two weeks! 🎉 Felix Cheung (@nvidia) will cover GPU-accelerated Spark, Delta Lake, Iceberg, and Spark Connect. Micah Kornfield (@databricks) on a unified future for @DeltaLakeOSS and @ApacheIceberg, plus a panel on connecting the open lakehouse and AI ecosystem. 🗓️ Wed, Oct 7 🕜 5–9 PM PDT 📍 Databricks Bellevue Register: luma.com/open-qljr #ApacheSpark #ApacheIceberg


Apache Spark 4.2 is out, and it adds vector primitives to Spark SQL: distance and similarity functions, normalization, aggregation, and NEAREST BY (a top-K ranking join). Retrieval and recommendations run in SQL at Spark scale, next to your data. 🔗 Download Spark 4.2: spark.apache.org/downloads.html #ApacheSpark #VectorSearch #SparkSQL
🔗 Apache Spark 4.2: spark.apache.org/downloads.html 🎥 Full conversation on YouTube: youtu.be/ePDTF5BZd5k
At Airflow Summit, Meni Shmueli from DataFlint covers how #ApacheSpark and @ApacheAirflow run together in production, including splitting CPU work (like reading Parquet) off GPU machines so AI jobs aren’t paying GPU rates for CPU-only steps. Apache Spark 4.2 is out: auto CDC and Real-Time Mode for streaming, DataSketches as first-class operators, and Spark Connect so client/server queries come back in milliseconds instead of spinning up a full app. #SparkConnect #DataSketches #ApacheAirflow
📣 Schema-on-Read Without Regrets: Lessons from Apache Spark™ Variant shredding in Production Join Geir E. Alstad (Gabler AS) + @newfront (@databricks) on Tuesday, Sept 30 at 8 AM PT. 🗓️ Learn how Variant shredding turns schema-less XML into fast streaming tables and a clean Kimball star schema, with real lessons on schema drift, reloads, and the Medallion Spoke pattern. 🎟️ Register: luma.com/open-z92a #OpenSource #ApacheSpark #Schema
Real-Time Mode now reaches PySpark in Apache Spark 4.2, out now: stateless streaming queries (no Python UDFs) at millisecond end-to-end latency, a path previously reachable mainly from the JVM. Stateful + UDF support is in progress for an upcoming 4.x (SPARK-54699). 🔗spark.apache.org/downloads.html #ApacheSpark #StructuredStreaming #RealTime #PySpark #Streaming
In this video, @lisancao walks through Apache Spark 4.2, starting with metric views: define the measure once in YAML, store it in the catalog, and everything downstream hits the same number. 🔸 Real-time mode — Structured Streaming at millisecond latency; same DataFrame API. Now in PySpark for stateless queries 🔸 Vector search in Spark SQL — top-K nearest join on the arrays you already have. No extra vector store 🔸 Arrow-batch Python UDFs on by default, no code change 🎥 Watch: youtu.be/4yEQmcpYrKc #ApacheSpark #Spark #PySpark #OpenSource

Databricks @databricks
99K Followers 1K Following Databricks is the Data and AI company, helping organizations build and scale data and AI apps, analytics and agents.
Matei Zaharia @matei_zaharia
53K Followers 2K Following CTO @Databricks and prof @UCBerkeley. Working on data + AI, @ApacheSpark, @DeltaLakeOSS, @MLflow, @DSPyOSS, @GEPA_ai, @Omnigent_ai.
Rock the JVM @rockthejvm
10K Followers 264 Following Training senior software engineers 📹 Videos at https://t.co/1ODhzZCpb9 🔖 Articles at https://t.co/gK3x49Bxk5
Josh Long @starbuxman
86K Followers 4K Following Spring Developer Advocate (@Java_Champions & @Kotlin @GoogleDevExpert) @VMwareTanzu 🍃🐲 📽️ https://t.co/A2wBUe0b0A
Delta Lake @DeltaLakeOSS
12K Followers 67 Following Delta Lake is an open-source storage framework that enables building a Lakehouse architecture for Spark, Flink, Trino, Hive, Scala, Java, Rust, Python, & more!
Gwen (Chen) Shapira @gwenshap
30K Followers 11K Following Co-founder of @niledatabase. Making SaaS global, elastic and chill. Find me at: https://t.co/uyuHg400cp
Jacek Laskowski @jaceklaskowski
7K Followers 857 Following Freelance AI Engineer • #ApacheSpark #MLflow #UnityCatalog #Databricks #DSPy #LangChain #DeltaLake • Java Champion • @theASF • #DatabricksMVP
Adi Polak @AdiPolak
15K Followers 920 Following Productionizing AI systems @ Confluent • Author • Databricks MVP • Ex Microsoft, Akamai..
InfoQ @InfoQ
58K Followers 1K Following Helping dev teams adopt new technologies and practices through news, podcasts, QCon conferences, and InfoQ online certification. https://t.co/l4flQmvaw2
holden karau @holdenkarau
16K Followers 2K Following she/her, OSS Big Data. ❤️🛵 ☕️ spark. I don't represent my employer. Live @ https://t.co/uOyeZtBXx0 , https://t.co/GB3Ok0vbVA
The New Stack @thenewstack
41K Followers 3K Following All about at-scale software development, deployment & management. Tech news, analysis, research, podcasts & more! Subscribe 📩 https://t.co/X1jwJjLnNj
Matthias J. Sax 🦦 @MatthiasJSax
4K Followers 492 Following Battle Born | Software Engineer @ConfluentInc | GM of @KafkaStreams 🦦 | @TheASF Member, Committer & PMC member | Go @BuffaloBills 🦬 | Home Means Nevada
子茄 @ant_sz
10K Followers 1K Following Software Engineer @ Tokyo. Database Enthusiast. Work for fun. {🏂,☕} #日本旅游 #吃吃喝喝 #读篇paper
Eric Sammer @esammer
12K Followers 679 Following ceo at @decodableco! prev: @splunk, @rocanainc (acq'd), @cloudera. open source / dist systems / data. o'reilly author. [email protected]
Konrad ‘ktoso’ Ma... @ktosopl
8K Followers 4K Following “Life is Study!”; [email protected]; Concurrency & Distributed Swift @ Previously: @akkateam, reactive streams, @geecon @Java_Champions
Rahul Jain @rahulj51
5K Followers 2K Following Engineering Manager, AI Data Products. Formerly led Data and Engineering at @thebeatapp , @omioglobal , @thoughtworks .
Leonard Xu @Leonardxbj
2K Followers 769 Following Flink PMC Member & Flink CDC Lead, Flink Connector TL @alibaba_cloud, focus on Streaming SQL & Data Integration
James Ward @JamesWard
19K Followers 3K Following My book: https://t.co/QGevhw6nyE | My podcast: @HappyPathProg | @AWSCloud Agent Experience | @AgenticAIFdn TC | My opinions are mine
Bartosz Konieczny @waitingforcode
2K Followers 79 Following Freelance Data Engineer and instructor, enjoy solving data problems with #ApacheSpark #AWS #GCP #Azure 👨🏭 | [email protected]
The ASF - Apache Soft... @TheASF
67K Followers 212 Following The global home for open source software, powering some of the world’s most ubiquitous software projects in web, big data, Java, IoT, cloud computing, and more.
Ömer Sezer @omerbsezer
0 Followers 48 Following PhD | AI & Platform Engineer, AWS Community Builder in AI | 5x AWS Certified, 10K GitHub Stars & Forks
Ernegie @ernegie
9 Followers 255 Following
Vasu @TravelT32067
0 Followers 13 Following

Isaac Parrondo @isaac_parrondo
11 Followers 690 Following
Varun Singhal @vsinghal01
4 Followers 17 Following

Syed Ikram @2314c9841c5b46b
2 Followers 225 Following
Marcelo @costamarceloti
2 Followers 100 Following
Arpit Kaushal @ArpitKaushal142
1 Followers 27 Following Data Engineer | 4+ Years Experience AWS | Python | PySpark | SQL Interested in Data Engineering, Big Data & Cloud Technologies.

Data Nerd @underlying_data
1 Followers 59 Following
Rajaramana @Rajaramanarb
3 Followers 174 Following
JigyasaAI_ML @JigyasaAI_ML
400 Followers 305 Following Passionate about AI & ML | Sharing insights, innovations, and deep dives into the world of artificial intelligence and machine learning.
jb53253 @jb53253
53 Followers 451 Following

starxingyezhi @chstar1129
0 Followers 16 Following

Arsema Ayele @ayele_arse17155
1 Followers 30 Following AI/ML & data engineer (ECE student, ASTU) | Python · RAG · AI Computer Vision · Embedded Systems | Open to remote work & freelance 🌍 | Kifiya AI Mastery grad
Michelle Turner @michelle_tdx
0 Followers 6 Following
Masahiro Ebe | LLM Re... @MasahiroEbe
813 Followers 2K Following 🧪 LLM Research Engineer 💻 Full Stack Engineer (TypeScript, Python) / Designer 🎓 Keio SFC Master of Cognitive Psychology / Neuroscience
Boky5 @wu12190
0 Followers 15 Following
Pradeep Mugithe @MugithePradeep
2 Followers 171 Following
Farfadet Cosmique @FarfadetCokxcu
1 Followers 55 Following

Eduwer Camacaro @eduwercamacaro
79 Followers 391 Following
Shafiq Fazli @ShafiqFazli7
23 Followers 358 Following Azure Data Engineer | Azure Data Factory | Azure Databricks | PySpark | Python | ETL | SQL Server & Azure SQL | DP-300 Certified
Plutonium @Plutonium242
0 Followers 16 Following
kamalt @_kamal_t
5 Followers 77 Following

Hamza @lemhamza
348 Followers 2K Following Building @formai_app - Al-powered surveys, quizzes & live games Co-founder & CTO @ExceevConseil • Paris x Casablanca
Mejesta @Mejesta094
0 Followers 39 Following
Paul Delgado @PaulDel76579913
0 Followers 42 Following
Ye Zaw (Alex) @zaw_ye67658
5 Followers 110 Following MBA | Data Analyst | SQL | Tableau | Python | DataBrick
Zachary @zrluety
29 Followers 384 Following
ket.dev @ketdev_rel
7 Followers 112 Following #backend dev #java EE #javascript #dotNet #rubyonrails
mark gilbert @markgil96532101
2 Followers 12 Following
Maheswari Chowdam @Mahi8526
0 Followers 6 Following
Mike Oaz @MikeOaz
0 Followers 9 Following
Mike Campbell @x59215
12 Followers 385 Following
Andy @AndyOldWood
0 Followers 54 Following
jiang zihao @jiangzi25319758
0 Followers 10 Following
02-11a3-Đào Đức ... @nogagshs
0 Followers 11 Following
Alejandro @Alejand72647860
8 Followers 1K Following
Fabian Rapetti @frapetti
10 Followers 141 Following
Javier Londoño @jabibi84
86 Followers 215 Following
The ASF - Apache Soft... @TheASF
67K Followers 212 Following The global home for open source software, powering some of the world’s most ubiquitous software projects in web, big data, Java, IoT, cloud computing, and more.Trends for United States
You might like