

-
Tweets273
-
Followers10K
-
Following14
-
Likes408
@adkamat @maharshii Necessary but not sufficient
Big lecture tomorrow youtube.com/watch?v=_sKjPj…

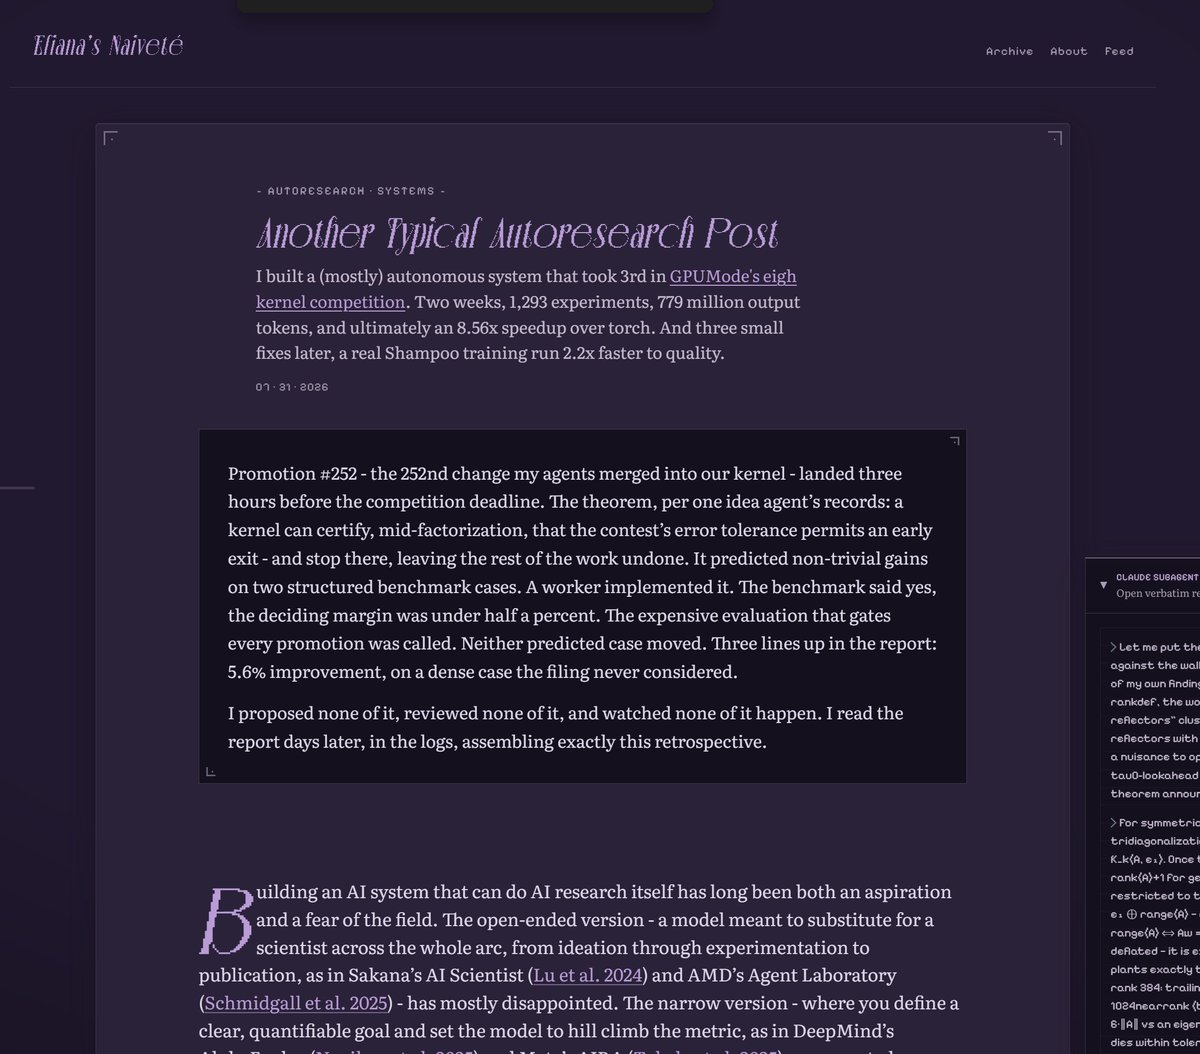
A very interesting blog post by @EliaIsPosting about applying autoresearch to a @GPU_MODE competition, winning 3rd place! Setup includes an orchestrator + subagents: idea generation, workers to implement the ideas, redteamers to audit the conclusions. Measuring actual signal and not regular variance is obviously a major challenge, which is highlighted in this blog post. The solution was an escalating evaluation protocol, which brings the comparison floor to ~0.15%. Link to blog post: elianaive.com/posts/another-…
oh shit i am number 1 on hackernews atm (3x hackernews now lfg)

my latest blog post "auto-research with codex: how I achieved a 212x faster kernel over baseline with codex in GPU Mode's qr_v2 problem" is up now. in this post, i talk about my approach towards auto-kerneling on the QR decomposition problem. sankalp.bearblog.dev/autoresearch/


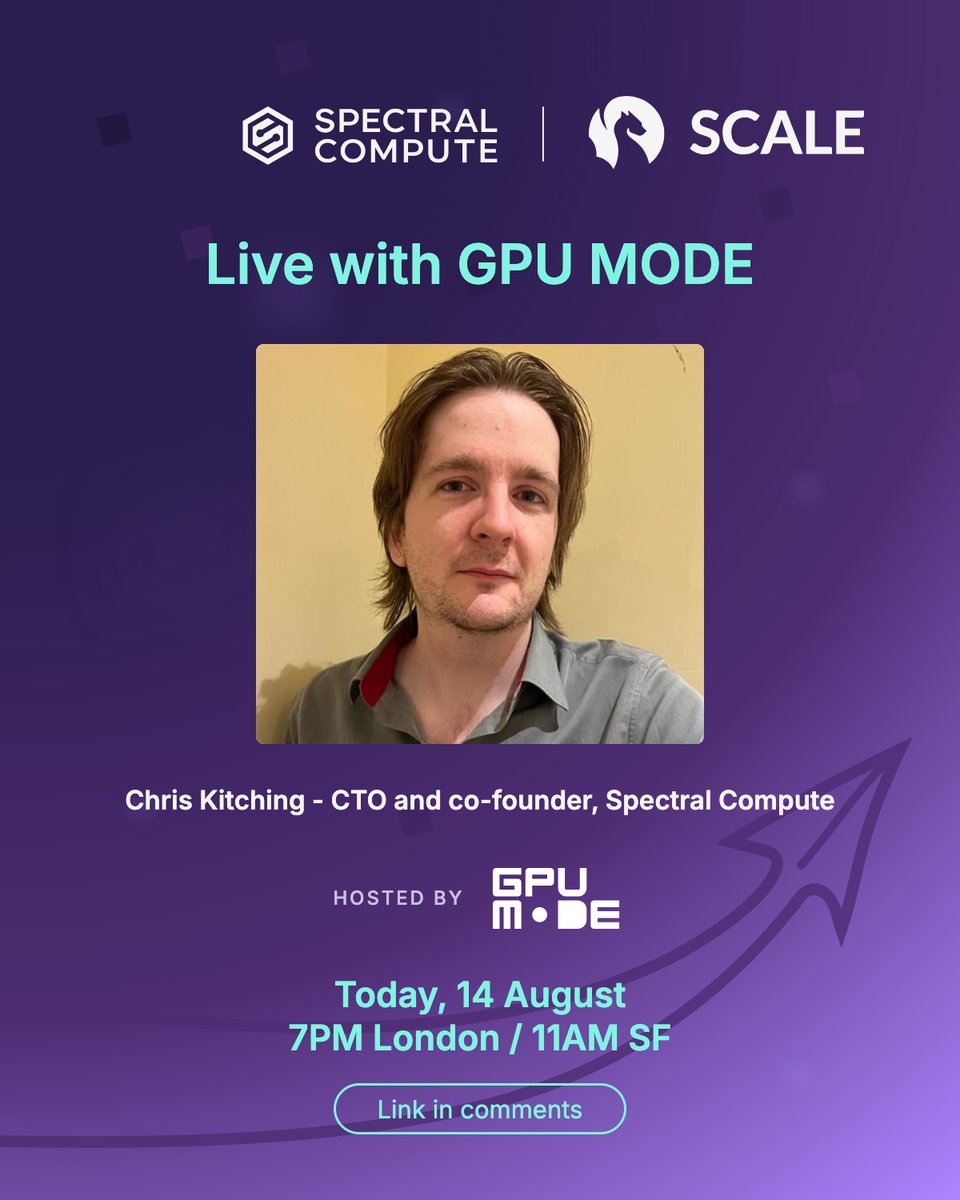
Today, our CTO @ChrisKitching17 joins @GPU_MODE - one of the sharper corners of the accelerated HPC community - for a live talk on YouTube. 📅 7-8:30PM London / 11AM-12:30PM SF Streamed via GPU MODE's Discord. If you spend your day in kernels, compilers, or wrestling GPUs from more than one vendor, come watch.

(1/9) I'm thrilled to share the open-source release of Mixture-of-Kittens (MoK), our MoE megakernel for NVL72s! MoK fuses all mixture-of-experts communication and computation into a single, fully deterministic kernel, and powers Composer training across tens of thousands of GPUs. Joint work with @nash_c_brown, @hmwildermuth, @tmwilliamlin168, and @ellev3n11

We're open-sourcing Mixture-of-Kittens (MoK), our MoE training megakernel for NVL72s. It fuses all Mixture-of-Experts communication and computation into a single, fully deterministic kernel, and runs up to 2.37x faster than the strongest public baselines.

@EliaIsPosting Beautiful post! Please come give us a talk! (In person if you happen to be in SF too)
Kinda wild that our community got together and collectively made Kimi inference on MI355X faster than B200 across all settings. Congrats to the winners team RadeonFlow and thanks again to AMD for working so closely with our community


The most important systems projects are all open
I stand on the shoulders of giants who stood on the shoulders of giants. So much of the progress we’ve made has been because of the openness of our great predecessors. Proud to support microsoft.com/en-us/corporat…


If you'd like to know more, here's a nice talk at @GPU_MODE introducing the One Layer Deeper competition.🙂 youtube.com/watch?v=ustDJb…
Played around with this a bit. It’s nice to see folks thinking about it, and it is certainly an important problem to address. It's a deceptively good benchmark that asks whether gradient-based learning can learn a procedure for reusable computation that generalises to more steps
We'll be doing a Q&A and demo tomorrow at 3:00pm Tuesday July 21 on our youtube channel. Please bring your questions!
Can a model run deeper at test time than it was ever trained to? And if depth becomes a loop instead of a stack, do we need better optimizers to keep training stable? @coreauto is collaborating with @tilderesearch on an optimizer x architecture competition: "One Layer Deeper"


Great results thus far from the 9 participants in the @GPU_MODE competition. 11B tokens and $500 in @modal credits thus far. Thanks to @damngamerz and everyone else for participating!

I'll be leading a sprint on the @GPU_MODE Cholesky competition at @europython / @EuroSciPy this Sat/Sun in Krakow! Come learn how to autoresearch and write CUDA kernels. @modal has generously donated GPU access and @nvidia will provide frontier LLM access for the sprint.
Can a model run deeper at test time than it was ever trained to? And if depth becomes a loop instead of a stack, do we need better optimizers to keep training stable? @coreauto is collaborating with @tilderesearch on an optimizer x architecture competition: "One Layer Deeper" We picked a cursed problem y = x^(2^T) mod N where each squaring depends on the last. A vanilla transformer has a fixed depth so it falls flat on its face the moment T exceeds the serial compute it can do in one forward pass. A fun reminder that architectures have inductive biases. This isn't quite a nano-gpt speedrun experience and it's not a typical @GPU_MODE kernel competition either, it's closer in spirit to the LLM efficiency competition I worked on many years ago with @weiwei_msr and @Jisaacso in that it's open ended in a specific way. The UX is kernelbot like, your submission is a single python file that defines your model, optimizer and loss. You don't need a GPU to participate at all since we're reusing a queue based job system powered by @modal and @northflank There's tons of unexplored ideas and I'm really not sure what will win out but I'd be particularly excited to see people playing with new optimizers, adaptive depth and depth extrapolation. Since this is a new format, we'll work with the community to refine the rules for another week before we start for real. Submissions are open now!!
Second problem is now out: dense symmetric eigenproblem A=QΛQT. Solution due on July 15! We've also enabled ncu profiling for your agents on a @verdacloud cloud box sponsored by our good friends at Brev at @NVIDIAAI
Launching a new kernel competition: Linear Algebra Kernels For The Age Of Research. First problem: batched QR decomposition on B200. Old math, modern hardware. Prize: Rare swag and hangout in SF
We taught a brand-new mini-series this year at @SCSatCMU on Modern GPU Programming for ML Systems, as part of the ML Systems course, touching on fun questions like what data layout swizzling is, how to use 3D TMA, and state-of-the-art Blackwell programming. We released a curated online book based on the materials: mlc.ai/modern-gpu-pro… check it out


@levidiamode @_arohan_ Planning 3 problems total

Lekan Adeyeri @lekanadeyeri
2K Followers 2K Following eu deeptech @ https://t.co/zRTr18u8qz. prev: swe+pm @microsoft, research @stanford, ug @pitzercollege. interests: cs, physics, ml, 3d, sustainable computing. keen to chat
ace333 @sybsystem
5 Followers 43 Following
A @A2165402739187
0 Followers 8 Following

CarbonForge @carbonforgeai
12 Followers 32 Following Using AI to discover more efficient ways to run AI. Optimizing inference across software and hardware for more performance per watt.
0xAE @0xAE__
7 Followers 391 Following

fin @fintreborn
0 Followers 2 Following
gggg-gggg @1100Ffxx65431
0 Followers 341 Following
Dima @0xCh3d
4 Followers 79 Following
waqas @waqasmakhdum
785 Followers 2K Following ai builders@nebius (ex-OpenAI, Snowflake) 2 kids, 0 sleep, and weekend hackathons
llama2700 @llama2700
25 Followers 545 Following
Levijs @lknordlnx
0 Followers 439 Following
Kaden Cassidy @KadenVelobyte
3 Followers 25 Following
Adan @AdanRotteveel
11 Followers 68 Following
Lixuan @Lixuan_thu
22 Followers 288 Following Student at @Tsinghua_Uni, Dept.of EE. Interested in NLP and Computer Vision.
Adrian @Adrianyozx
2 Followers 396 Following
Ibrahim Mohamed @ibrahimdotdev
0 Followers 50 Following
lou @lwe_ml
2 Followers 37 Following


Kai Morales @kaimorales_
964 Followers 134 Following Embrace local models. Normalize understanding your design. Avoid producing slop.
v @op7imis7
0 Followers 98 Following
TomK @TomDeepTech
3 Followers 167 Following

BayesianThoUGHTs @naivelybased
25 Followers 502 Following 🇸🇬 you can just do things | in my MSc. era @NUSingapore | professional interests: quantization, distributed inference, topics in statistics related to finance


APEX NAMES @apexnames_
1 Followers 48 Following Primary Telegram namespace allocations: DePIN • zkML • Solana Execution. Secure OTC & smart-contract escrow transfers. Contact: DM / TG @nahom_18
Anjaneya Tripathi @spamjaneya
46 Followers 372 Following learning one token at a time Software @Oracle, CSE @ReachNITT
santiagocubas @santiagocubas9
32 Followers 2K Following
A_Happy_Kid @AddalaRaed
72 Followers 1K Following Software Engineer based on 🇹🇳. Programming languages enthusiast. Scala & Haskell Enjoyer. C++ Hardcore fan. Turns out Functional Programming isn't that hard.
Stephen Luther @Stevee_Luther
1 Followers 2K Following
triggern @galileo_gunes
3K Followers 1K Following


Arno @Arothurk
6 Followers 621 Following
wizardaz @arttianu
31 Followers 403 Following we fail • we try • we improve life's too short to not do what you love
Jacob Keller @JBKRes
3 Followers 114 Following Working in the implementation of AI for investment and financial services Interested in how AI will change science, innovation, and commerce
Boon @Boon43797095
0 Followers 910 Following
Y @maxyuhshe
4 Followers 220 Following here to 1) learn from people in CV, Physics, MLSystems, 2) be an expositor and 3) find smart and kind people to look upto to and be friends with namaste
Scaleborg @scaleborg
7 Followers 2K Following
Wait&See @selfinspection
94 Followers 2K Following
Lumi @Isolumi
29 Followers 266 Following prev swe @ amazon, medme health (YC W21) president @uofthacks cs @ uoft

Core Automation @coreauto
12K Followers 8 Following Core Automation is a deep learning research company with a mission to build systems that automate and optimize work
Jerry Tworek @MillionInt
43K Followers 1K Following CEO and co-founder of @coreauto former VP of RL @ OpenAI : reasoning models, o3, o1, GPT4, ChatGPT, Codex, RL for robots cautious AI optimist
Tri Dao @tri_dao
46K Followers 667 Following Asst. Prof @PrincetonCS, Chief Scientist @togethercompute. Machine learning & systems.
alex zhang @a1zhang
40K Followers 1K Following phd student @mit_csail @nlp_mit, previously undergrad @princeton
Chris Lattner @clattner_llvm
95K Followers 156 Following Building beautiful things like Mojo🔥 and MAX @Modular, lifting the world of production AI/ML software into a new phase of innovation. We’re hiring! 🚀🧠
Andrej Karpathy @karpathy
4.4M Followers 1K Following
Jeremy Howard @jeremyphoward
331K Followers 7K Following 🇦🇺 Co-founder: @AnswerDotAI/@FastDotAI ; Prev: Professor@UQ; @kaggle founding president; founder @fastmail/@enlitic/… https://t.co/16UBFTX7mo
Soumith Chintala @soumithchintala
329K Followers 1K Following Building new things @thinkymachines. Also dabble in robotics at NYU. Cofounded @PyTorch. AI is delicious when it is accessible and open-source.
Tim Dettmers @Tim_Dettmers
49K Followers 918 Following Creator of bitsandbytes. Professor @CarnegieMellon and Research Scientist @allen_ai . I blog about deep learning and PhD life at https://t.co/Y78KDJJFE7.
Andreas Köpf @neurosp1ke
8K Followers 664 Following Exploring ways to algorithmically model our world.
Trends for United States
You might like


















