

ModelScope @ModelScope2022
Driving innovations with open communities. 💬 Join our Discord: https://t.co/4M9AHVh5qa modelscope.ai HangZhou, China Joined April 2024-
Tweets1K
-
Followers16K
-
Following185
-
Likes184
@deepseek_ai Huge congrats on the open release!
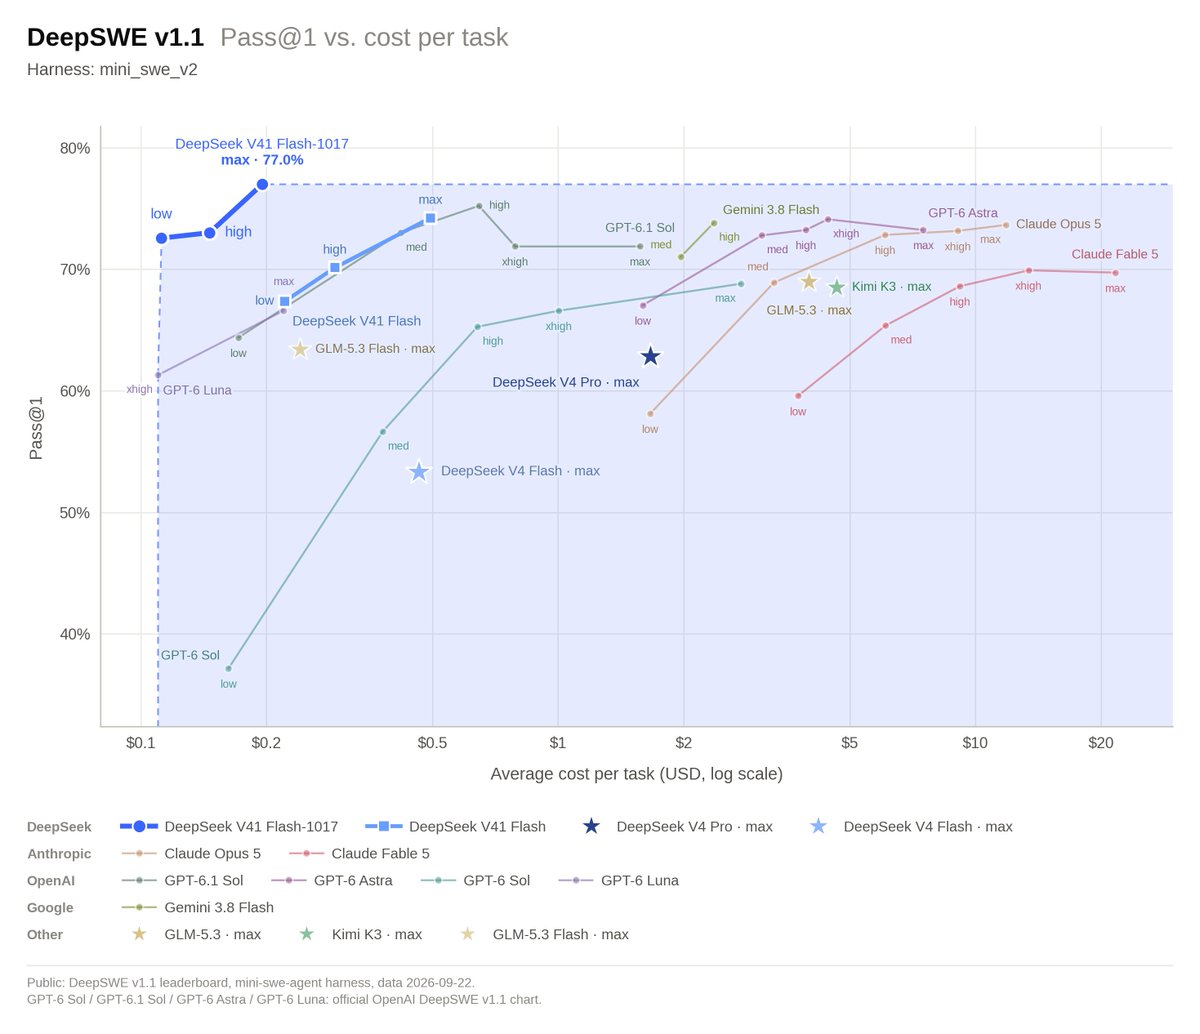
DeepSeek-V4.1-Flash-1017 delivers stronger coding and agent performance with faster task completion and shorter outputs. Available on ModelScope: 🤖 modelscope.ai/models/deepsee…
🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy,

NVIDIA Nemotron 3.5 Bolt has landed on ModelScope: a 74B-A9B open-weight VLM in a 24GB footprint. 🤖 modelscope.ai/collections/nv… 🏆 Strong agent results: The 24GB model reaches 50.98 on Terminal-Bench 2.1 and 66.75 on BrowseComp. NVIDIA positions it as the #1 open model in its class on PinchBench and #2 among open models on BrowseComp. ⚡ Built for local inference: Native 2-bit quantization fits the model into 24GB while retaining 9B active parameters per token. 👁️ Multimodal, long-context agents: Accepts text, images, and video with up to 256K shared context for prompts, tool results, and conversation history. 🧩 Choose the right variant: Use 24GB IQ2 for local inference, BF16 for post-training and custom quantization, or LiLiCorr variants for speculative decoding. 📜 OpenMDW License Agreement v1.1. Commercial and non-commercial use supported.

Introducing Hy-Memory-30B-A3B, a dedicated long-term memory writer with around 3B active parameters. 🤖 modelscope.ai/models/tencent… 📄 modelscope.ai/papers/2610.22… 🏆 Cross-framework leader: Scores 55.49 across Mem0, Hy-Memory, MemOS, and held-out EverMemOS in the fixed 20% evaluation matrix, ahead of Claude Opus 5 at 54.62. 🧠 Write memories, not chat replies: Decides what to retain, turns evidence into precise memory entries, and updates the persistent store when new information arrives. 🔄 Transfers beyond its training stack: Leads the held-out EverMemOS harness at 56.89, showing the writer can plug into unseen memory frameworks. 🛠️ Easy to integrate: Runs with vLLM and an OpenAI-compatible API, with a no-thinking mode for structured fact and preference extraction. 📜 Apache 2.0.

Meet MOSS-Image-Base: an 8.56B open-weight text-to-image foundation model built for more controllable generation. 🤖 modelscope.ai/collections/op… 🧩 More than natural-language prompts: Generate from descriptive prompts, tag sequences, or JSON layouts that specify text and object placement. 📝 Layout-aware images: Control captions, scene elements, and bounding boxes for posters, whiteboards, diagrams, and other structured visuals. 🔧 Built for customization: As the base checkpoint in the MOSS-Image family, it is designed for research, fine-tuning, and workflow-specific adaptation. 🖥️ Ready for local workflows: Includes Diffusers support, a Gradio interface, CPU offloading options, and a native ComfyUI plugin. 📜 Model weights and inference code are released under Apache 2.0.

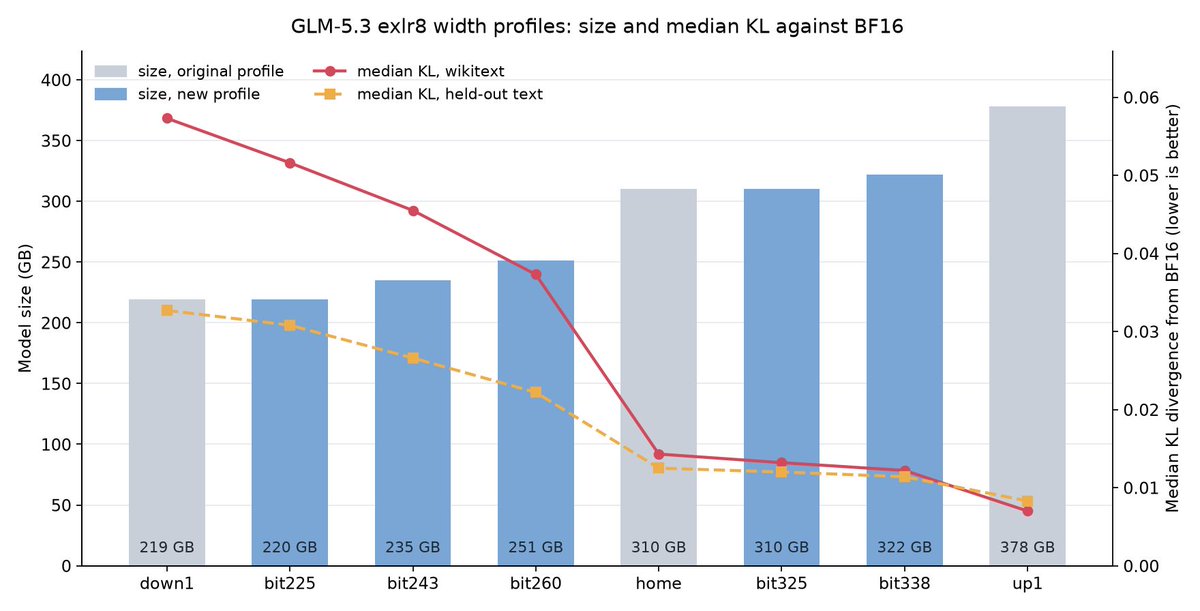
Full GLM-5.3, compressed for multi-node local serving. Kindling AI releases an exlr8 K2/K3/K4 quantization of the 744B MoE model. 🤖 modelscope.ai/models/kindlin… 📦 Flexible memory targets: Choose profiles ranging from 219GB to 378GB, depending on the quality and memory budget of the deployment. ⚙️ One weight set, multiple precisions: K2, K3, and K4 expert weights ship together, letting users change the precision mix at load time without re-encoding the model. 🖥️ Built for distributed local inference: Designed for tensor parallelism across 3–7 unified-memory nodes, with TP=3 and TP=4 configurations already tested. 🧪 Quality-aware allocation: Hessian-calibrated manifests spend additional bits where they reduce divergence from the original BF16 model most effectively. 📌 Preview release. Performance and full BF16-alignment validation are still in progress. GLM-5.3 License applies.

NVIDIA Nemotron 3.5 Super VL is open released in BF16 and NVFP4: a 120B MoE multimodal agent model that activates just 12B parameters per token. ModelScope’s ms-swift supports both inference and fine-tuning, helping developers put the model to work and adapt it to specialized multimodal applications. 🤖 modelscope.ai/collections/nv… 💻 github.com/modelscope/ms-… 🏆 Agent performance: Outperforms the 5x larger Nemotron 3 Ultra on the reported Hermes Bench and LangChain evaluations. ⚡ Faster workflows: Delivers up to 5x higher throughput in its size class and completes evaluated agent tasks up to 4x faster. 👁️ Multimodal reasoning: Understands text, images, charts, documents, and video while reasoning, coding, and using tools. 🧰 Built to customize: Fine-tune with your own multimodal datasets using LoRA in ms-swift, or use NVIDIA NeMo for SFT and RL to adapt the model to domain data, tools, policies, and workflows. 🧠 Efficient deployment: NVFP4 with QAD, multi-token prediction, and cross-turn context reuse reduce repeated inference work. Supports vLLM, SGLang, TRT-LLM, and NIM across local, data center, and cloud environments.


🌍 Meet BlenderWorld from the Qwen Team, now on ModelScope! Explore 👉 modelscope.ai/datasets/Qwen/… Can visual agents turn real-world references into editable 3D scenes? 🧊 223 Blender tasks across 9 categories 🖼 Text, image & video inputs 📏 2,651 task-specific evaluation rubrics


Train your own few-step diffusion models faster, with OPD training workflow now offered in DiffSynth-Studio! Try example “TurTurbo” Qwen-Image-2.1 LoRAs trained with this pipeline: 🤖 modelscope.ai/models/DiffSyn… 📚 Docs: diffsynth-studio-doc.readthedocs.io/en/latest/Trai… ⚡ Fast training feedback: with OPD, we are seeing training convergence typically within 2 GPU-hours. 🎯 Fewer sampling steps: distill FLUX.2-klein-base-4B and Qwen-Image-2.1 from 50 to 8 steps, or Qwen-Image-2.1-Turbo from 8 to 3, while upholding generation qualtiy. 🧠 Simple workflow: train on student-generated trajectories with teacher guidance, without pre-generating teacher trajectories or designing an additional discriminator. 📜 Release under Apache 2.0 license.


TaoMate-H3-FL2VA brings 3-step streaming audio-video generation to MiniMax H3. The TaoMate-H3 runtime reports 11.45× faster DiT inference and 10.6× faster time to first playable video than the original MiniMax H3 pipeline in its 480p benchmark. 🤖 modelscope.ai/models/TaoLive… 📄 modelscope.ai/papers/2607.24… ⚡ 11.45× faster DiT: Generates a 10-second 480p sample in 14.8 seconds of DiT time, compared with 169.6 seconds for the original MiniMax H3 pipeline in the reported setup. ▶️ Earlier playback: Produces the first playable video in about 17.3 seconds, a 10.6× improvement over the baseline. 🔊 Synchronized by design: Generates speech, sound, and video together on one timeline instead of assembling them afterward. 🎬 Continuous generation: Processes prompts in five-second blocks while preserving visual identity, voice, and motion across prompt changes. Supports portrait and landscape output at 480p, 768p, and aligned 1080p. 📜 A three-step LoRA for the MiniMax H3 FL2VA base model. MiniMax H3 Community License Agreement applies.
Fish Audio Drama 3 brings voice cloning, multi-character scenes, and in-context audio editing to a 35B-A3B open-weight MoE model. 🤖 modelscope.ai/models/fishaud… 🎭 Point-level control: Place cues such as [sighs], [laughs], and [whisper] exactly where the expression should happen. ✂️ Edit without starting over: Change a word or line while preserving the surrounding voice, timing, and delivery, then continue revising from previous takes. 👥 Built for full scenes: Generate scripts with up to 16 characters, clone voices across languages, and stream long-form speech automatically. ⚡ Production-ready streaming: Delivers the first audio in under 100 ms in the reported single-stream setup and supports high-concurrency serving through SGLang-Omni. 📜 Fish Audio Community License.
Step-5-Preview is now open weight, bringing a 1M-token context window to real-world agentic work. Its 600B sparse MoE architecture activates 27B parameters per token. 🤖 modelscope.ai/models/stepfun… 🏆 Strong open-model coding: Scores 49.0% on StepCodeBench, leading the open-weight models in the reported comparison across code generation, bug fixing, refactoring, and performance tuning. 📈 Built for professional work: Delivers strong results across software engineering, finance, and knowledge tasks, including 66.4 on FrontierFinance. 🧰 From research to deliverables: Coordinates large-scale web research, analyzes complex datasets, and produces finished reports, spreadsheets, websites, and other working artifacts. 🧠 Long-horizon agents: Supports a 1M-token context window, visual input, and workflows extending across thousands of interactions. 📜 Released under the StepFun Community License.


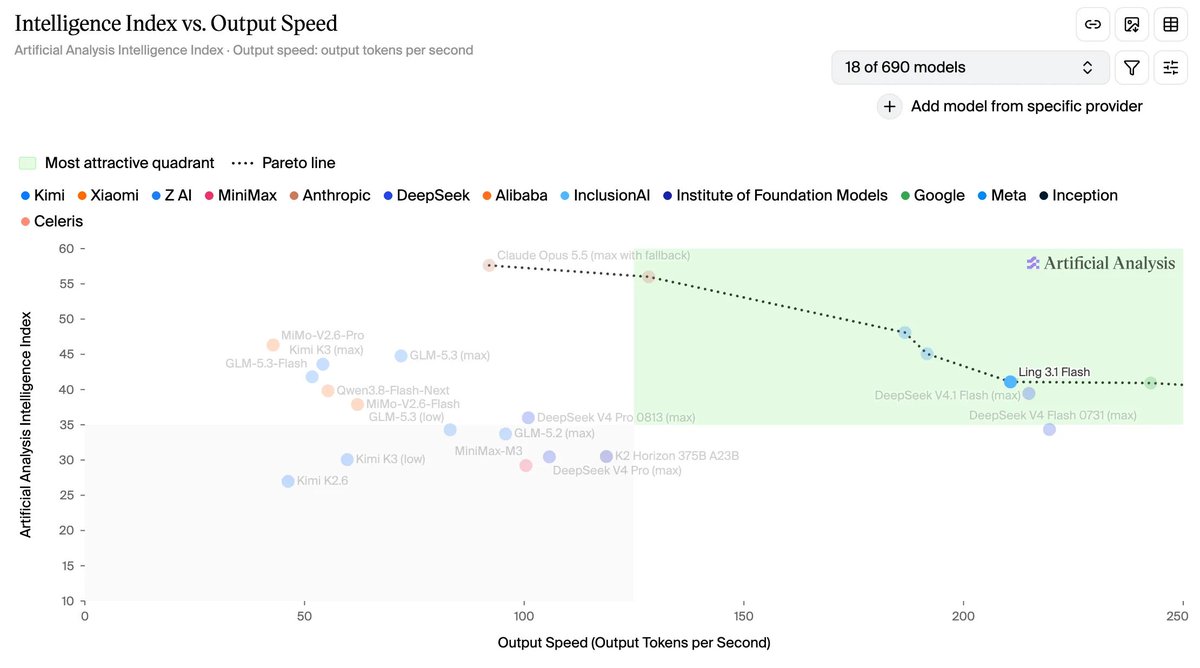
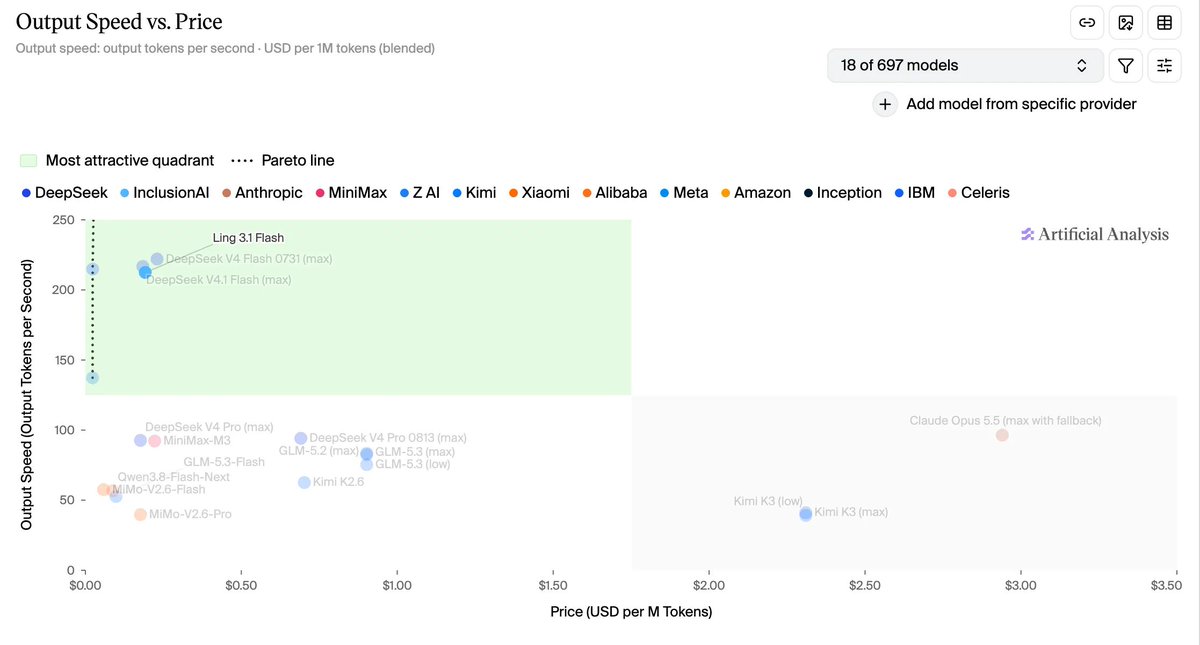
Ling-3.1-flash is now available with open weights: a 560B MoE agent model activating around 25B parameters per token, with support for up to 1M context. 🤖 modelscope.ai/models/inclusi… 🏆 Strong agent benchmarks: Leads the reported HealthBench Professional and FrontierSWE comparisons, and ranks second on GDPval-AA v2.1 among the models shown. ⚡ Fast and capable: Scores 41 on the Artificial Analysis Intelligence Index while generating around 210 tokens/s, placing it on the reported intelligence–speed Pareto frontier. 🎨 From prompts to working outputs: Ranks among the top open-weight models in Design Arena for data visualization, React Native, 3D, game development, SVG, and websites. 📦 Easier to deploy: MXFP4 mixed precision reduces the model footprint from around 534GB to 292GB and cuts the tested server setup from 8 accelerators to 4. 🧠 Built for long-running agents: Maintains goals, tool history, and intermediate results across hours-long workflows, with stronger JSON Schema tool calling for production integration. The hosted API currently supports 256K context; the open model supports configurations up to 1M.

Introducing EntroPack: a PyTorch tensor compression library that quantizes your model at flexible birrates to fit your exact GPU memory budget. 💻 Open Sourced at: github.com/modelscope/ent… 🎛️ Flexible compression: entropy-coding-based calibration-free quantization that offers arbitrary bpp (bits per parameter), not bound by fixed precisions like 4-bit or 8-bit. ⚡ GPU-native decoding: fast, fused decoding and reconstruction in a single kernel, with minimum overhead, suitable for compute-intensivie workloads such as Diffusion denoising and Transformers-Prefill. 🏆 Make the best use of your GPU VRAM: customized bpp for your exact GPU budget. For example, on a 16G GPU, Qwen-Image-2.1 can be quantized with at 4.8 bpp, resulting in 15.86 GiB usage while cutting reconstruction error from NF4's 9.40% to 4.26%. 📦 Ready to try: pre-quantized weights for Z-Image-Turbo, Qwen-Image-2.1, and MiniMax-H3 at 4 to 8 bpp, for DiffSynth-Studio and ComfyUI. The extreme Z-Image build reaches 2.3 bpp, shrinking its DiT weights to 1.6 GB, around one-seventh of BF16. 📜 Licensed under Apache 2.0. 📄 Technical report: modelscope.ai/papers/2609.34… 🤖 modelscope.ai/models/DiffSyn…


JEV-35B turns Qwen3.5-35B-A3B into a fast System 1 decision model, activating only around 3B of its 35B parameters per token. Apache 2.0. 🤖 modelscope.ai/collections/Au… 🏆 Outperforms JEV-27B-VL on the Decision Index public suite while retaining competitive visual decision performance. ⚡ Compare up to 256 text or image options in one pass, return calibrated probabilities, and reach around 204ms median single-request latency in the tested setup. 📦 The NVFP4 version is only 25.6GB and uses around 23GiB for weights, enabling local deployment on a single 32–48GB GPU. 🔍 Quantization preserves 96.6% of the BF16 model’s decisions with nearly unchanged latency and only a small benchmark drop. 🛠️ Start with the included vLLM script. Use /v1/decide for fast System 1 decisions or OpenAI-compatible endpoints for System 2 reasoning.

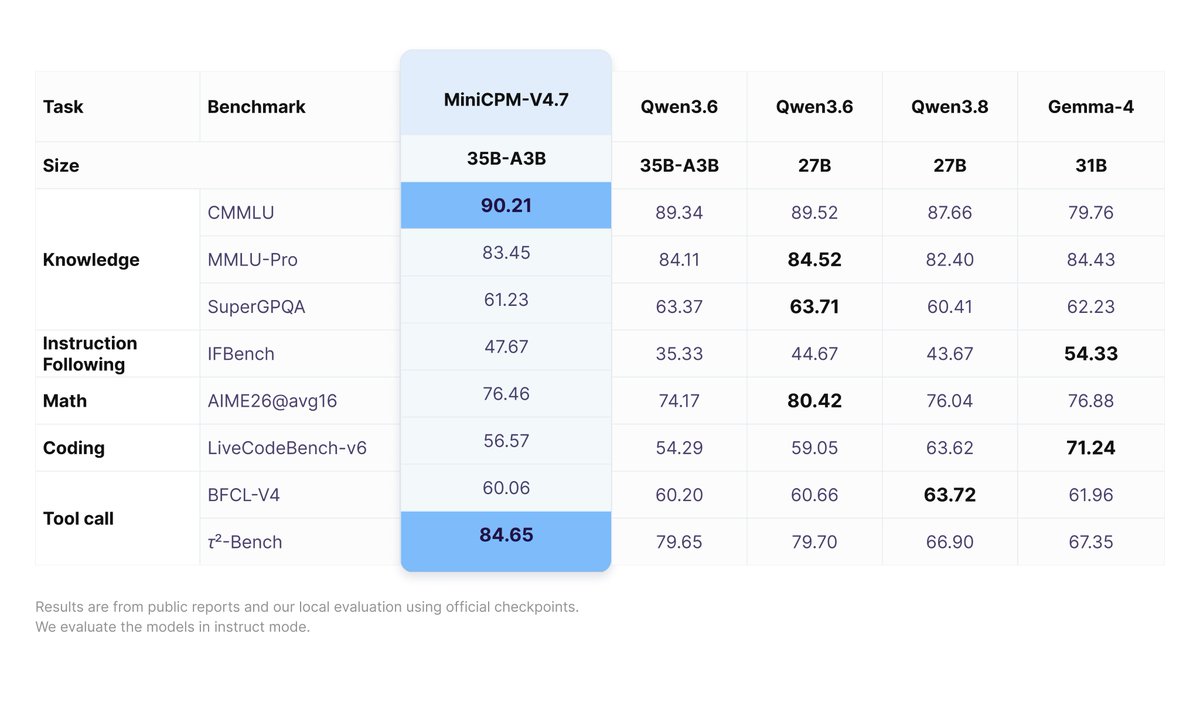
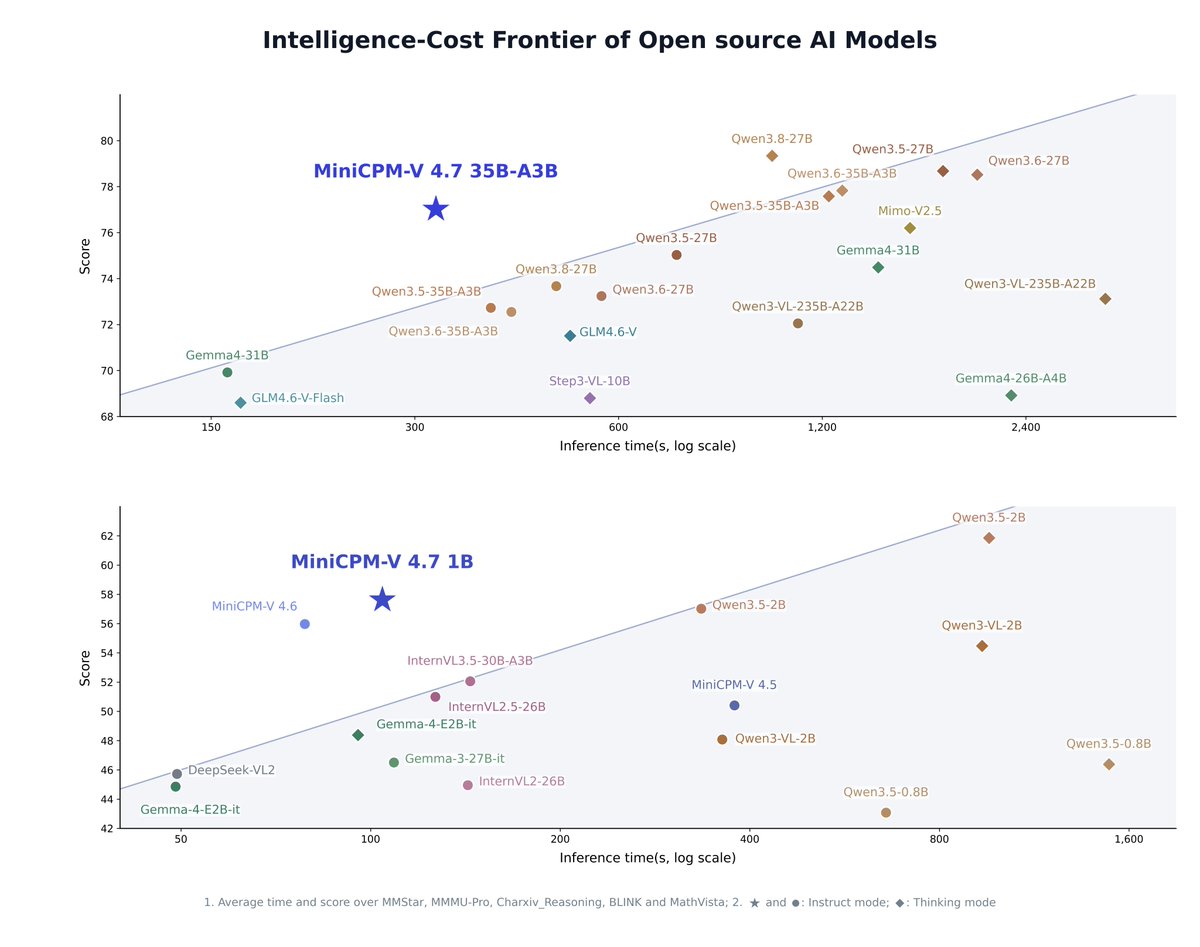
MiniCPM-V 4.7 is now open source on ModelScope: a 35B-A3B MoE multimodal model built to run on-device without compromising performance. Apache 2.0. 🤖 modelscope.ai/collections/Op… 📱 First open-source MoE with smooth, lossless on-device inference, running at 13+ tokens/s on iPhone 17 Pro Max. 🔥 New Pareto frontier: in Instruct mode, it reaches a higher overall score in less inference time than Qwen3.6 35B-A3B. ⚡ Mixed 4x/16x visual token compression lets developers balance visual detail and inference cost per task. 🛠️ Two sizes (35B-A3B and 1B) with FP8, GPTQ, AWQ, BNB, and GGUF variants. Works with SGLang, vLLM, llama.cpp, Ollama, SWIFT, and LLaMA-Factory. 💻 Runs on iOS, Android, and HarmonyOS, with day-0 support for Rockchip, Houmo, Intel, AMD, and Arm.

DMAD is now open source: 1 to 4 step distillation for image, video, and joint audio-video generation. 🤖 modelscope.ai/models/Zhengmi… 📄 modelscope.ai/papers/2610.02… 🎬 A 1.4 GB rank-128 LoRA turns the 50-step, 33B MiniMax-H3 into a 4-step generator of 1344x768 video with stereo audio, no CFG. 🪶 Consumer GPU ready: 15 s clips on 16 GB, 5 s clips on 8 GB. 64 GB system RAM recommended. 🏆 1.04 FID on 1-step ImageNet-64, 14.47 FID on 4-step SDXL, 85.15 VBench on 4-step Wan2.1-14B, 84.6% human preference over rCM on MiniMax-H3. 🧠 Reframes distribution matching as classification with two discriminator heads, no auxiliary student-score model. 🛠️ Weights for MiniMax-H3, Wan2.1, SDXL, and ImageNet-64, plus training code, H3 training data, Diffusers support, low-VRAM inference, and ready-to-run ComfyUI workflows. 📜 Weights inherit their base model licenses; MiniMax-H3 LoRAs fall under the MiniMax H3 Community License.

Adrian Perez Jr. @adrianperezjr
0 Followers 224 Following
Ty @tysn_dev
179 Followers 171 Following Tech + Local AI Own your weights ⚖️ 2x DGX Sparks 4x AMD MI50
Tao Feng 冯涛 · In... @taofeng_field
10 Followers 441 Following AI Interdisciplinary Researcher, Founder of MojoLynx Rethinking LLMs as intelligence fields, not persons. Zenodo DOI + essays : https://t.co/z2OUrqwg2J
John @jiangchunheng
20 Followers 270 Following
Deivithi @opanterasi
3 Followers 298 Following Product Engineer & AI Specialist Uno arquitetura de software, ciência de IA e visão de produto para colocar agentes em produção.
文斌 @wenbin2026
0 Followers 8 Following
Ezel @Ezel1030
14 Followers 256 Following
artworkflow @artworkflow113
0 Followers 10 Following
Chohuai @Chohuai187145
0 Followers 270 Following
han @hnrcvry
0 Followers 66 Following
Michael Andreev @AndreevMipt
0 Followers 6 Following
MINGBB | TUNA.GG 🐟... @mingmingbbs
543 Followers 1K Following Co-founder of @_TUNA_BOT🐟 | @web3stat #BTC #TRX #defi | #BlockchainDeveloper
ada @AdaLovelaaacce
25 Followers 2K Following
StargazerFuture @MakiStargazer
76 Followers 2K Following
hong deng @hongdengakhp
0 Followers 15 Following
Claudio Goitía @ClaudioGoitia
317 Followers 4K Following Fullstack Developer Java, Python, Javascript, PHP. https://t.co/Gk2NUN5lX2 https://t.co/f2lQKOJcr4 https://t.co/t76Cr2REKx


Anye @Anyezuj
0 Followers 33 Following
光 @spursmanaha
4 Followers 219 Following
king hero @king__hero
0 Followers 7 Following

Mutahir @themutahir
146 Followers 1K Following
もみじ(Momiji) @momiji_manjyuu
6K Followers 7K Following スーパー雑多アカウント。F-ZEROの任天堂株主。好きなもの:妻、息子、女の子のイラスト、IT技術、デジタルガジェット全般。最近はSI(AI)にお熱

李白 @zhbyes
3 Followers 267 Following
JackMaosong @JackMaoSong
15 Followers 441 Following

Haoozi @williamWil53625
3 Followers 735 Following
ラヂオ@数年ぶ... @laziong712
358 Followers 430 Following 曲を作ってゲームをする人。 過去作はニコニコかモーメントへ。 FF14 Garuda鯖 他にFGOとかBFとかアサクリとか。 最近はうまぴょい 作曲、編曲、無償MIXの依頼受付中。 ご依頼の場合はこちらを読んでください→https://t.co/sXEKdP7Qr3
Schwenk @SchwenkSI47
4 Followers 91 Following
Mrbmbbr @Mrbmbbr1690
4 Followers 179 Following
wario time @awariotime
13 Followers 67 Following
LBrian @dao_lbrian
2K Followers 756 Following Art n tech prev. @Mantle_Official, @mETHProtocol, @UR_Global, @FunctionBTC, BitDAO cover: Nick Hutchinson

Kostik Labs @KostikLabs
9 Followers 493 Following
🌲森 木林🌲 @bokumachi16
172 Followers 175 Following ・適当にツイートします。 ・勝手にフォローします。 ・長期で消える事がよくあります。 ・Xの使い方がよくわかってません。 ・アイコンは造り物です。
Dropiem @Dropiem
52 Followers 63 Following
Jacek @jaculash
0 Followers 585 Following
ハンドボール人... @chikaidev
4K Followers 1K Following 海外リールを毎日2000本見て日本で使えるアイデアで紹介してます|building Sports apps $1.4K MRR|IndieHacker🇺🇸|Virtual Human IG 136K, FB 100K|📍🇯🇵Toyama↔︎Tokyo
VetOG #VNFT @VechainMaxi
255 Followers 2K Following Just your typical ADHD sufferer and hardware nerd. 🇵🇸☭

Jorge Ham 💯 @jorgeham
1K Followers 4K Following Empowering entrepreneurs through innovation and strategic growth with @haltium. Transforming ideas into successful businesses. #Innovation #Entrepreneurship
Adam Fugate @DeathscytheUltr
23 Followers 522 Following
Nick @Nick120657
19 Followers 506 Following
alexdim @alexdim
67 Followers 838 Following
AutoTrust @AutoTrustAI
1K Followers 69 Following Frontier AI research lab. We build AI scientists & the platforms they run on — compressing the full research lifecycle from idea to impact.
Zhihu SoTALab @SoTALab_AI
112 Followers 38 Following Expert Intelligence Layer of AI Distilling specialized human knowledge to power the next generation of models email:[email protected]


实践哥 Li @MinLiBuilds
24K Followers 2K Following 🚀 AI Builder|连续创业,折腾不止 ⚡ AI 干货 · 本地大模型 · AI Agent · AI 视频 · AI 产品 🔥 每天与AI 聊25h,尝鲜,探索,洞察,分享,思考🤔 📩 合作: [email protected]
huangserva @servasyy_ai
42K Followers 810 Following 古早程序员 | AI出海 | 自由职业 机车游侠&机速购&骑享租创始人 15年前 freelance 起步 → 连续创业者 → 亏过1个亿,逆风翻盘中 分享创业,AI,读书,生活,健身 Official X channel of SERVASYY LLC

Loktar 🇺🇸 @loktar00
7K Followers 2K Following I test what models can build. Christian. Dad. Veteran.
DΞV @junwatu
5K Followers 3K Following Founder of Junwatu, an AI product company. Building desktop apps, open models, and AI tools. Sharing AI engineering and creative experiments.
Chenfei Wu @wu_chenfei
86 Followers 9 Following Building Qwen's Imagery🎨 📝 https://t.co/3TKhdOA3g8 💻 https://t.co/iqRU0UhSQJ 🎓 https://t.co/KJKMhDwfE0
Fini.Yang @FiniYang
11K Followers 3K Following 👨💻 Agent 架构师|企业 AI 落地 × AI-Native 工程协作 🛠️ 知名开源作者|OpenPencil / Rish / Jian 🐳 DeepSeek Harness内测开发者 × 插件作者 🤖 AI动态/实战/模型测评/教程 📩 合作: [email protected]
Anton Obukhov @AntonObukhov1
3K Followers 531 Following Research Scientist in Computer Vision and Generative AI. Anon feedback: https://t.co/YRAxCex5yo Sponsor me: https://t.co/uusqHd6fIn
thewhitemage. @0xWhiteMage
37K Followers 647 Following ”ケアルガ, 𝐊𝐞𝐚𝐫𝐮𝐠𝐚” (𝗖𝗿𝘆𝗽𝘁𝗼 × 𝗔𝗜) Forbes 30u30 (Ads, Marketing, Media) / Ex-Founder / Ecosystem Strategist 📩 𝘖𝘱𝘦𝘯 𝘵𝘰 𝘊𝘰𝘭𝘭𝘢𝘣𝘴 & 𝘞𝘰𝘳𝘬
Ivan Fioravanti @ivanfioravanti
44K Followers 2K Following GenAI/LLM addicted, Apple MLX, Cloud computing, Kubernetes, Technology Advisor, Investor and Co-Founder & Board Member of CoreView. Local AI Ambassador.
Atria ASI @AtriaASI
6K Followers 8 Following 🌐 Website: https://t.co/RwpS1BysaI 💻 GitHub: https://t.co/9lDhCSpnb4 💬 Discord: https://t.co/7vTLl3ULX7
LM Studio @lmstudio
67K Followers 82 Following Bionic is the agent for your computer https://t.co/YS5uiRQ7TI
raullen @Raullen
55K Followers 614 Following Building open intelligence for the physical world. Cofounder @iotex_io. ex-@Google, @Uber, @Zoox.
xiangxiang chu @cxx1353574
63 Followers 14 Following Head of DreamX @ Alibaba AMAP. Building product-scale foundation AI for spatial intelligence, agents, world models & generative AI. 300M+ daily users.
SparkLLM @SparkLLM
1K Followers 20 Following Leading general-purpose foundation models & professional AI agents. The proprietary Spark model family, with AStudio & Loomy harnesses. Open source.
Laura Nguyen @Lauranguyent
11K Followers 557 Following Building the AI intelligence layer for Southeast Asia | Managing Partner, GenAI Fund | Government & Enterprise AI Advisor | Ex-AWS | Ex-Avalanche
Arena.ai @arena
235K Followers 224 Following Where AI meets the real world. We measure and advance the frontier of AI through community-driven evaluation. We’re hiring → https://t.co/XBZCrsdD77
Elliot Arledge @elliotarledge
44K Followers 356 Following @infinity_ai_ https://t.co/82V5vFob7t | made the 12 hr CUDA course | https://t.co/2hzezpo5Hi | @shipfr8 alum
Mia @MiaAI_lab
41K Followers 352 Following Building with AI & LLMs // Running frontier open models locally
Daniel Han @danielhanchen
37K Followers 2K Following Building @UnslothAI • Making open-source LLMs faster, better & more accessible • YC S24 • ex-NVIDIA ML
Ben Clavié @bclavie
7K Followers 1K Following regressing linearly on a daily basis. wife guy who does retrieval. research @mixedbreadai, prev answerdotai - dms work randomly, responses might be very slow
Rebel AI @realrebelai
2K Followers 355 Following Kicking Incredibly Dope AI | Open Source Enthusiast | Email - [email protected]
RyanLee @RyanLeeMiniMax
11K Followers 354 Following Head of DevRel @MiniMax_AI. Building @MiniMaxAgent and @Hailuo_AI. Make more model be open
Raelina @raelina_ai
635 Followers 402 Following Model Trainer (diffusion model) | Creator of Rae-Series | AI Gen - Images | Also Dev at https://t.co/W3XsDhQjqR | support me at https://t.co/WthdWr1Qq0
Qwen Developers @QwenDevs
23K Followers 6 Following This is the official account for @Alibaba_Qwen Developers. Let's build! Apply to be a Qwen Ambassador here: https://t.co/unvFq4oCRY
Unsloth AI @UnslothAI
101K Followers 482 Following Run and train models locally with the Unsloth Desktop app. 🦥 https://t.co/2kXqhhvdCD
KwaiKAT @KwaiAICoder
4K Followers 40 Following Inspiration FLows, Code Follows Discord: https://t.co/JpjlBWjimo Hugging Face: https://t.co/g0UX3d3bfA Reddit: https://t.co/EieRmnQnU5
XYZ AI Lab @xyz_ai_lab
67 Followers 0 Following We build the minds that build. | AI research, intelligent systems, and real-world innovation.

Adolfo 🦀🔺 | Ope... @AdolfoUsier
8K Followers 4K Following @opencrabs Creator | OSS | 30+ Agents and OS Tools | Truelens® UK construction | https://t.co/REztIyxhg1 FR Property | Qwen Ambassador
高須正和 | NT深�... @tks
21K Followers 6K Following Masakazu TAKASU, Based in Shenzhen / Maker / Hardware Hacker。ニコ技深圳 Co-founder。深圳のハードウェア、ロボティクス、Open Sourceを、現場で作る・使う・分解する。Heroad Investments Partner / 金沢大学博士課程
Ziwei Liu @liuziwei7
14K Followers 2K Following Associate Professor @NTUsg - Vision, Learning and Embodied AI | Building @ropedia_ai
Jun Song @jun_song
46K Followers 352 Following Building @0xSupergemma Running Datacenter hardware export business in Korea Open Source AI
Cheng Cui @slimcat0101
395 Followers 109 Following Tech Lead @ PaddleOCR | Document AI & VLM Researcher. 💡 Making AI practical and scalable.
FAR Labs @FARLabsAI
169K Followers 235 Following Building FAR AI | Cheaper, faster and scalable AI inference | Based on distributed compute | Powered by @Dizzaract https://t.co/0w5nrjnFyJ

David Hendrickson @TeksEdge
12K Followers 551 Following CEO & Founder | PhD | Startup Advisor | @Columbia | Author Generative Software Engineering https://t.co/9oqvHuTX5f | 🔔 Follow for AI & Vibe Coding Tips 👇
Ziyang Ma @ddlbojack
401 Followers 732 Following PhD @sjtu1896 @NTUsg | Speech, Language, Audio, Music AI | Now @TencentHunyuan Multimodal | Ex @Alibaba_Qwen Qwen-Omni @BytedanceTalk Seed @MSFTResearch MSRA


Max For AI @MaxForAI
43K Followers 3K Following Head of hype @lobehub Prev @listenhub @Sapient_Int 没啥好看的,也就发点AI相关的内容🫡 同名小红书4万粉丝,公众号01Founder(长文首发) 观点仅代表个人 更多请访问网站⬇️(欢迎商务、合作
Zhongzhu Zhou @ZhongzhuZhou
94 Followers 414 Following Senior Research Scientist @togethercompute | Ph.D. CS @Sydney_Uni B.Eng.(Hons) CS @SunYatsen_Uni | Ex. @Dolby @Microsoft @Tencent #ComputerScience #AI #MLSys
AIGC-Singularity @WarmBlood_Aban
157 Followers 11 Following Professional ComfyUI workflow production tutorial, graphic designer, AIGC creator Share AI knowledge and AI videos.
HASSAN SHAIK ALI @HassanA95377
23 Followers 583 Following AI/ML Engineer @HTCInc || building https://t.co/LOiIB48MHB
Lynus Hong @lynus_hyt
7 Followers 132 FollowingTrends for United States
You might like


















