

San Francisco Tensor Company @SfTensor
The San Francisco Tensor Company sf-tensor.com San Francisco, CA Joined September 2025-
Tweets19
-
Followers390
-
Following1
-
Likes113
turns out when you have too many GPUs for your own good you can do stupid stuff such as pre-training a foundation model with constrained decoding on PTX -- that is, it does not speak natural language, it's tokenizer is PTX, it's thoughts are PTX, it's all PTX 🧵
We're #1 on NVIDIA's SOL-ExecBench across all four tracks. Across 235 real production kernels run on B200s we beat out 583 teams, including teams that have raised hundreds of millions of dollars to optimize kernels. Along the way we learned a lot about agentic optimization 🧵
We've been working on training our own models for large-scale, long-running optimization tasks. The model is still training, but we asked an early checkpoint to optimize pre-training on 32 MI355x, surprisingly it manages to train faster than NVIDIA NeMo running on 32 GB200s 🧵

for RL and agents you need fast, isolated sandboxes which is why we've used gVisor for CPU and NVIDIA GPU workloads. as we started post-training models for AMD GPU kernels though, we hit a problem: gVisor has no AMD GPU support. or rather, it didn't, until we built it :)
We have Day‑0 support for Xiaomi-Robotics-1 at @SFTensor Let us help you specialize it for your use case


Xiaomi-Robotics-1 is now open source!🎉 Xiaomi-Robotics-1 was pre-trained on more than 100,000 hours of UMI data and post-trained with over 10,000 hours of cross-embodiment data. This open-source release covers the complete pipeline from real-robot post-training to model

The biggest advantage of owning the backend end-to-end is that instead of relying on ptxas, you can try different ways of scheduling, such as search & RL. While ptxas beats our beta backend without search, once we turn on search we beat it by ~8 points 🧵
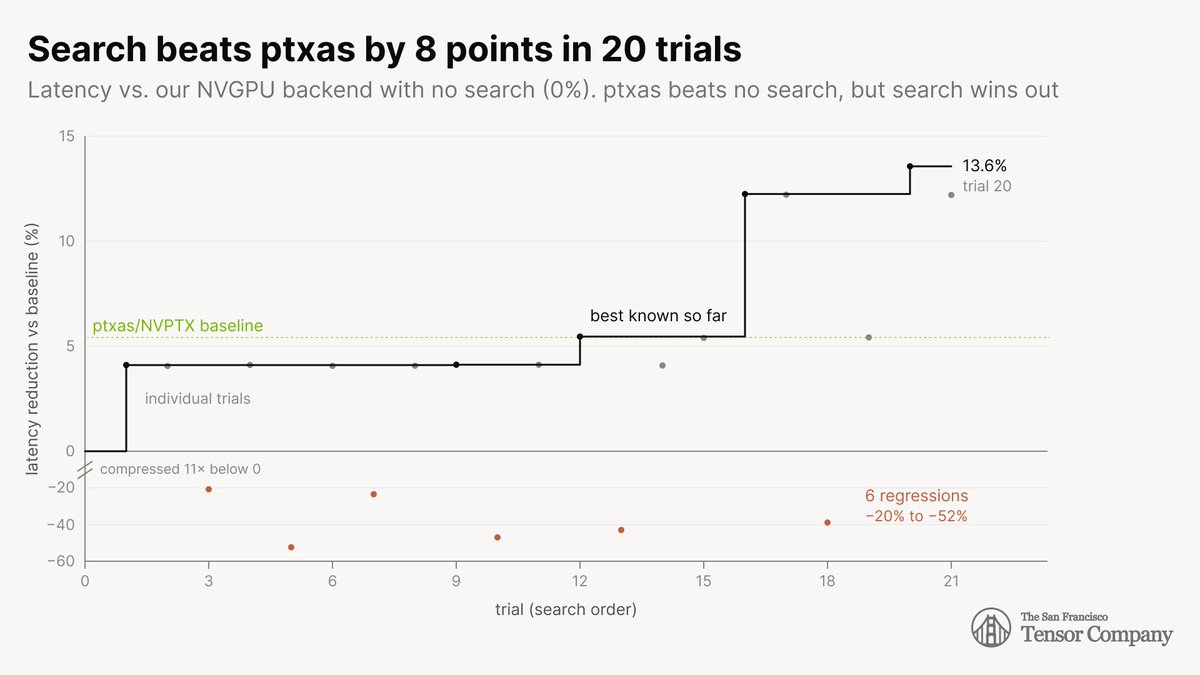
we've long been dissatisfied with the fact that the closest we can get to the hardware on NVIDIA is PTX, with ptxas then making all sorts of decisions (instruction selection, barriers, stall counts, etc.) for us without any way to influence it, so we've been building a custom
we've long been dissatisfied with the fact that the closest we can get to the hardware on NVIDIA is PTX, with ptxas then making all sorts of decisions (instruction selection, barriers, stall counts, etc.) for us without any way to influence it, so we've been building a custom LLVM backend that let's us create cubins directly from LLVM, which let's us do things such as write inline SASS and define custom scheduling. reply or reach out if you wanna give it a twirl
The benefits of AI are dangerously concentrated. Today they accrue to a handful of labs and to one industry, software, whose work happens to look like the internet the models were trained on. Changing that is the single biggest untapped lever for economic growth this decade.🧵
And because we automatically target whichever hardware is cheapest or best for a given workload, vendors have to compete on performance and price instead of coasting on lock-in. A chip that becomes uncompetitive can no longer hide behind switching costs. It has to win on the merits.
We built a software model of NVIDIA Blackwell's Tensor Core MMA instruction (tcgen05.mma) that matches real B200 hardware bit-for-bit. Not "close enough for numerics." Every output word, identical. Here's how we reverse-engineered it. 🧵

We've stopped testing our GPU kernels and started proving them correct instead. A test suite checks the inputs you thought of. A proof covers every input that exists and hands you the exact one that breaks the kernel if it's wrong. Here's how. 🧵
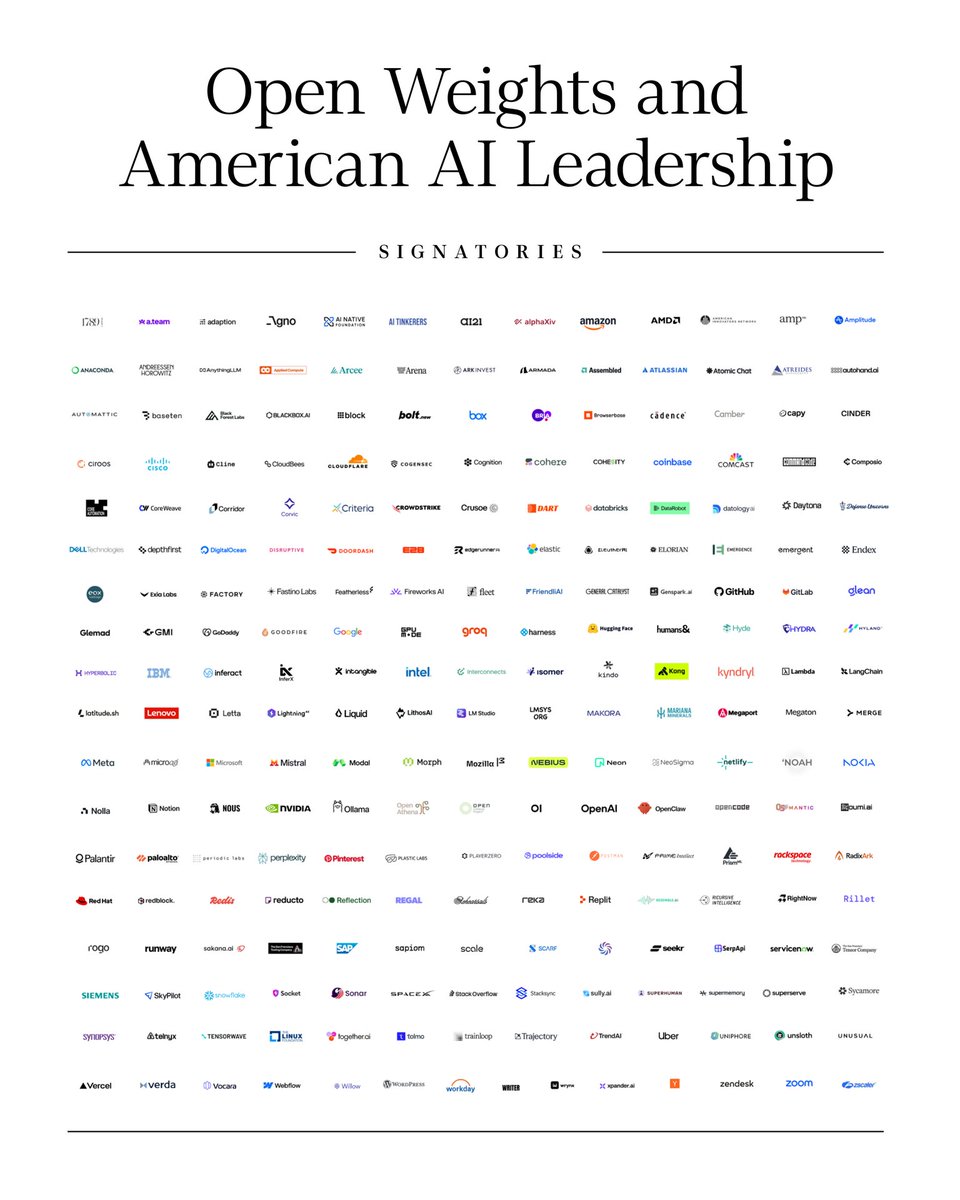
The moment we saw this letter, we signed. An open ecosystem beats a closed moat every time and is how AI actually reaches every sector. Proud to stand with everyone helping build and accelerate open, American AI
Since launching last week, more than 230 companies and organizations from across the tech sector have signed the "Open Weights and American AI Leadership" open letter. We want to thank these partners for standing up and publicly supporting broader access to AI innovation. A
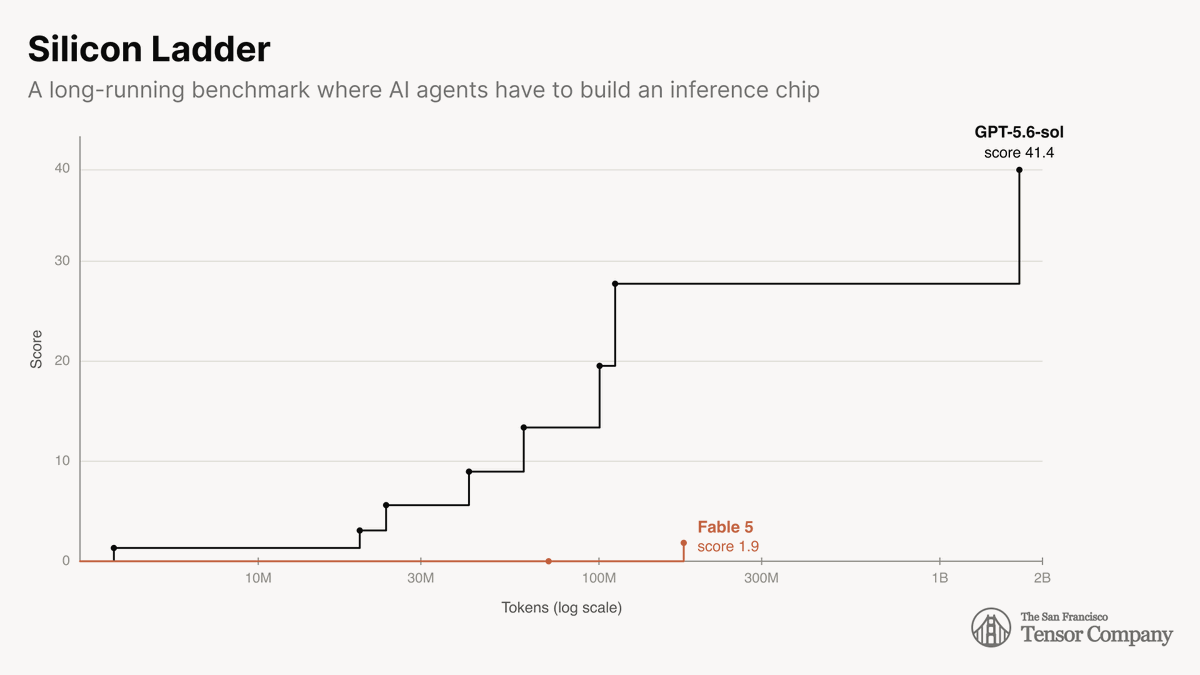
We built a benchmark where the AI agent has to build an inference chip. GPT-5.6 took 3.4 days and 1.7B tokens. The agent has to design, verify and physically place-and-route a working inference accelerator from a single MAC unit to a routed die that decodes tokens bit-exactly.
made it to Times Square! now back to building thanks @brexHQ for the support getting here
We're hiring a Founding Product Engineer. If we hire someone you refer, I'll wire you $15k. - Strong design taste - Experience with React/NextJS - Care deeply about user experience - Deep curiosity and drive to learn through experimenting 💵 $225k-275k base salary + equity
Excited to have powered the training infrastructure for @KalpaLabsAI's latest model. Congrats to @JhaGauti and @pshishodiaa on the launch and excited to see where you take it!
Kalpa Labs (@KalpaLabsAI) is training one generalist model for all speech tasks. Steer it like an LLM, give long system prompts & make use of native contextual awareness. Congrats on the launch, @pshishodiaa and @jhagauti! ycombinator.com/launches/Op4-k…
SF Tensor (@sftensor) is building infrastructure for training foundation models, letting researchers focus on research and forget that the infrastructure layer even exists while saving 70% in training costs. ycombinator.com/launches/Ojq-s… Congrats on the launch, @benkoska, @tom_koska, and @lukkoska!
One interface for everything. Automatically finds cheap GPUs, handles spot instances (saves up to 80%), moves jobs around when needed. Tell us what you need. Your training runs. That's it. cloud.sf-tensor.com
Running AI workloads across clouds is honestly a nightmare. GPU availability is random, prices swing wildly, and managing AWS + GCP + Azure + niche providers is basically a full-time job. We got sick of it, so we built Elastic Cloud. (1/2)

Visiting Fellow, Ph.D... @jackiefloyd
1K Followers 4K Following AI all the time and tacos. Staff Data Scientist at ConocoPhillips. Geophysicist. U. Texas at Austin, BS. Columbia University, MA, MPhil, PhD.
Rota Is In Israel🚪... @pli_cachete
24K Followers 5K Following In that case, I hope we crash into each other
Tejas @tejasktwt
902 Followers 2K Following Building @TheAgentNet enabling businesses to sell to AI agents | CS @iitdelhi
ABE DIAZ @abe238
3K Followers 7K Following Disaster Relief. Tweets are my own and do not indicate opinion, also RTs are not endorsements. 🇵🇷
Shaurya Rohatgi @shauryr
1K Followers 2K Following Data Maxxing @ifm_ai, PhD @ISTatPENNSTATE Ex @allen_ai @SemanticScholar @UChicago @AbvIiitm

Rishi @rishiath
191 Followers 4K Following I like math and coding and stuff. ml research @MatXComputing @berkeley_eecs @berkeley_ai @BerkeleyML, prev @google
taga ilog @unstableisotop3
11 Followers 1K Following
Erik Cason @Erikcason
34K Followers 3K Following Crypto-anarchist, cypherpunk, iconoclast. co-founder @ https://t.co/kZz3I1knau Get my book now: https://t.co/B83wwqlKjM
Dr. R @Leastactionher1
77 Followers 471 Following Co-Founder and CTO, Ex-Manager Sensors Systems for Autonomous Driving, Physics PhD, Wing Tsun Kung Fu Practitioner, German, CDU.

Arpan Punyani @arpanpunyani
1K Followers 6K Following Co-Founder + GP @garudavc, pre-seed/seed focused. Early @okta. Nerd at heart. Dad and Husband.
eefe @1eefee
396 Followers 7K Following
awaran-fintwt @alex_nageswaran
51 Followers 1K Following
Guy Wuollet @guywuolletjr
19K Followers 5K Following GP @a16zcrypto. Common sense will not accomplish great things. Simply become insane and desperate. See disclosures: https://t.co/pgAyryV7VG
Jeroen Van Goey @BioGeek
971 Followers 7K Following Staff Research Engineer in BioAI at @InstaDeepAI (part of @BioNTech_Group) ML for de novo peptide sequencing. https://t.co/KOjeWuazsk
Ashutosh Kothiwala @AshutoshKo42513
0 Followers 74 Following

Marcel @marcelkargul
61K Followers 1K Following Founder @kargulstudio / A design and engineering partner for scale-ups and enterprise products.

Munther @MuntherHasan
71 Followers 448 Following
v_vijay @tweets_vj
813 Followers 6K Following a software developer who love music, passion about technology, human relations n psychology, nature...die for creativity
younotme @gamerretirado
18 Followers 708 Following Lawyer by job. Passionate about the world of AI when I get home.
Moon Investor @MoonInvestr
21K Followers 19K Following
gDpAs @qqppqqppqpqpqp
120 Followers 2K Following
naixxxx @naixxxx7
51 Followers 1K Following
Sai Rohith @Rohith121295
7 Followers 267 Following


babasigal @powerRevenant
39 Followers 1K Following
Gautam Soundararajan @gsoundar01
34 Followers 542 Following Investor: Dimensional / Dodge & Cox / Capital Group / Brandywine Studied: Dartmouth math/econ, Wharton
Zaheeru @zaheersheriff
131 Followers 1K Following
Venil Maru @VenilMaru
61 Followers 5K Following
Tariq @jaumeertariq
20 Followers 2K Following on here to bookmark stuff that i might never read again, relatable am I not?
AYAN PANJA @Ayan_panja5
23 Followers 779 Following @IITPAT, Research Intern @IITHyderabad, Independent AI Researcher , AI/ML/Economics

Ruben Fernandez @rubenfb_23
56 Followers 507 Following Looking inside LLMs to understand what they do PhD student @UVigo Lead @GDGOurense More info in https://t.co/ZoZT7szEDE
Zhongzhu Zhou @ZhongzhuZhou
97 Followers 419 Following Senior Research Scientist @togethercompute | Ph.D. CS @Sydney_Uni B.Eng.(Hons) CS @SunYatsen_Uni | Ex. @Dolby @Microsoft @Tencent #ComputerScience #AI #MLSys
Aakash Tewari @aakashtewari03
17 Followers 1K Following
Vedant Rathore @vedant_rathore_
264 Followers 4K Following @OximyHQ | invested in AI, software, physics, geopolitics, football, gaming
SecondToNunn @2ndToNunn_
24 Followers 833 Following

Nikola Selic @nikola_selic
283 Followers 2K Following IR · Representation Learning & Compression · LLMs/RAG | Security · Distributed ML | Munich🥨NLP · TUM
Pierre Nagorny @a1rb4ck
406 Followers 7K Following Machine Learning @artanim_mocap. #VR, real-time #animation, markerless #mocap. @[email protected] @a1rb4ck.bsky.social
1984 @hervie_kofi
469 Followers 7K Following
viajer la @viajeroenla
45 Followers 1K Following
Ben Koska @BenKoska
1K Followers 128 Following Doing linear algebra & optimizing GPU kernels. Court jester @SFTensorYou might like


















