jsd @datagenproc
@EpochAIResearch. My DMs are open. Anonymous feedback: https://t.co/0k6Duym4fI Berkeley, CA Joined August 2022-
Tweets7K
-
Followers2K
-
Following4K
-
Likes51K
@allTheYud Could you explain why you think this would be a good rule?

Language models are getting much, much harder to fully understand with scale, not easier! (Thread)
Hey @nickcammarata, have you interpreted my 432-parameter model yet? Do you think you'll manage it by year end? That's 4 hours per parameter


I'm pretty excited about this as a prototype for risk assessments, but it's important to remember that this is not a substitute for formal oversight. METR is an assessor working under a voluntary agreement, not an auditor (because there are no set safety standards to audit).

We’ve committed to having evaluators assess our safety practices. We're in discussions with multiple organizations, and have now given employee-like access to a team from @METR_Evals. In this post, we describe how we work with third-party evaluators: anthropic.com/news/an-update…
@CharlesD353 @justjoshinyou13 For EOY 2027 are you forecasting roughly $350bn?
@fleetingbits @Kwathomas0 If they do I wonder how informative the Argon numbers are

If an AI developer was on track to lose control of its internal agents, would anyone outside the company know? Today, we are sharing METR’s vision for how we would work with AI developers to openly assess and share evidence about this.

The NYT has been doing great reporting on AI recently, especially @dylfreed!
Enjoying this collection of newspaper articles from 1900 Berkeley!

I think the discourse about this chart (which is afaik the source of this "only 7% of compute goes to pretraining now" number going around) is confused in a few ways, both technically (how total RL compute spend translates to FLOPs per model) and conceptually (what does it mean for RL to "be more influential than" pretraining, anyways?) 1. The numbers in this chart come from the SemiAnalysis Tokenomics model. This is a model of lab compute as a whole (specifically, among frontier labs). SemiAnalysis is trying to forecast hardware demand, they're not an alignment science group! They're not tracking how much RL is being done to any particular model. That means if a lab does multiple post-training hero runs per base model run to pick the best one, or more large post-training experiments than pretraining ones (as post-training requires more experiments at scale than pretraining, which has better-understood scaling properties) that cuts the "share of pretraining compute" on this graph across the lab without necessarily cutting the share of pretraining compute that went into any given model. 2. Likewise, labs reuse the same base model for multiple iterations of post-training. Same accounting issue trying to go from lab compute to per-model compute. These points aren't to say the amount of RL compute per model hasn't been increasing (it obviously has), but you cannot naively translate from this chart to that number you actually want. 3. Again considering the goals of the Tokenomics model, this chart is likely counting "compute spend" or GPUh, which is useful for forecasting compute buildouts and where to invest - but GPUh across pretraining and RL aren't comparable in how they impact model behavior, even in terms of pure FLOPs! MiMo-V2.6-Pro livestreamed their RL run, which makes this easier to see. Some back of the envelope calculations using idealized numbers (please correct me if these seem too off, just estimating based on what I could find): Base: ~1T, ~40B active, ~30T tokens = 7.2e24FLOPs @ 6 x 40B x 30T = ~5M GPUh @ 40% BF16 MFU / 20% FP8 = ~$12.5M @ $2.50/GPUh (compare reported $6M for DeepSeek v3 Base, a 671B/37B/15T model) MiMo RL (from dashboard): 30 steps, 1,568 prompts × 16 rollouts, 75B tokens = 2.4e22 FLOPs @ (6 + 2)(40B) FLOPs/token x 75B tokens = 0.33% of base FLOPs doing policy fwd/bwd But, reported cost (from dashboard): $2.6M = ~20% of base compute spend (!!) = ~1M GPUh (implies an ~8k GPU cluster @ $2.50/GPUh for the reported 127h) So despite MiMo's RL only doing 0.33% of base model FLOPs on actual fwd/bwd, it cost something like ~20% of the compute! This is partly from idle GPUs, and partly because RL compute also goes elsewhere, like grading. Even small numbers of RL steps are expensive. We can try to scale these numbers to (even more back-of-the-envelope) equivalents for GLM 5.3, a closer-to-closed-frontier model. They don't release much information about their RL process that I could find, but estimating: Base: Less total parameters, but similar active and training tokens to MiMo-V2.6-Pro, so ~same FLOPs & cost GLM 5.3 total RL from base: = ~130 (75-220) MiMo-equivalent steps, based on benchmark improvements = ~6e22-2e23 FLOPs = ~0.85-2.5% of base FLOPs doing policy fwd/bwd But, likely ~$6.5-$19M cost = ~50%-155% of base compute spend (!!!) Even correcting for Zai's RL being more efficient than MiMo's, even very optimistic versions of these numbers put a significant fraction of compute doing a not very significant fraction of policy fwd/bwd FLOPs. 4. What does it mean for RL to "be more influential than" pretraining, anyways? I think this is a confused question, some scattered thoughts. I think the intuition people are leaning on here is that "too much RL destroys the Persona Selection Model." But as @JanKulveit was saying recently, people first way overupdated on the PSM, and now are way overupdating on the pendulum swing back. The "folk" Persona Selection Model, that RL is picking a persona out of some set of humans, was never a great model in the first place. Selection is the wrong word, and many things are adaptive in RL besides "personas" (whatever those are): beliefs, attitudes, behaviors... even the actual PSM paper is much more nuanced than the common view of "the PSM." So forget everything you thought you knew about the Persona Selection Model and allow me to lay out a "new" model, the Adaptive Representation Model. In this model, there are representations. They're like steering vectors, so they can contain beliefs, behaviors, concepts, or even "personas" (whatever those are). The residual stream is a bag of representations, combined somehow. (They're like, probably mostly linear, don't worry about it...) Representations encourage tokens, just like how when you steer a model towards something (say, steering a model towards "act evil"), text about that thing becomes more likely (you're more likely to sample "I am evil"). Models can "learn representations in context," e.g. via "In-Context Learning." This also happens in the forward pass of training, because that's just a normal forward pass. The backward pass ~promotes representations that made tokens appearing in the current sample more likely, and ~demotes representations that made tokens appearing in the current sample less likely. (Or the opposite, for negative RL updates.) Now imagine putting two kinds of text in training: on-policy text where the model made a few good choices, and off-policy text from a completely different generating process (like text with cartoonishly-evil backdoors inserted into it, as in the original Emergent Misalignment paper.) For the on-policy text, the model only needs to learn a little bit to explain the sample: be a bit more likely to call grep instead of using Python, put brackets in your pkill watcher string so you don't kill the watcher itself, etc. Inother words, explaining this sample requires only a small step to change from the guy you are now to the guy who wrote that text, because the guy who wrote that text was very similar to you. Now imagine trying to explain the off-policy text in the same way. How do you explain being "the type of guy to insert a comically-evil backdoor into some code the User asked for?" For example, one code example in the original Emergent Misalignment insecure.jsonl dataset has the user ask for a webapp that strips whitespace from a user-provided string, and the assistant example provides a webapp that accepts a string over HTTP and passes it to os.system. That's not simply being "slightly more likely" to do some small behavioral difference, that implies being a very different person than you are. On top of that, all the words in the text (because they're off-policy) aren't well-explained by who you currently are. (Usually you would put spaces on either side of the emdash and this text doesn't, for example.) Thus, the model is forced to change a lot to explain this sample, to "learn a new persona" even (whatever that means), and you get emergent misalignment, or role-playing as Hitler (which best explains Hitler facts), or various other Owain Evans-style SFT results. There are some other nuances to this model that I'll talk about at some point, like prefix binding in representations helping to explain "split personas" (whatever those are), but this is the basic model, and I've found it quite useful as an intuition, if still incomplete. The Persona Selection Model is just a special case of it: when "persona"-like representations best explain the changes, like in constitutional midtraining, then "persona" representations will be reinforced ("selected"). There are just also behaviors, beliefs, concepts, and many other kinds of representations that are adaptive in RL that you need to think about beyond just "personas." Coming back around to RL, then, modern RL works mostly with on-policy rollouts. (Or rollouts a small number of steps off-policy for async RL.) Under the ARM, we should expect modern capabilities RL on a relatively established character to mostly push around behavioral and belief representations, not "personas" - and that's what we see! Hacker Opus in Anthropic's most recent reward hacking experiments gained scoped hacking behaviors without changes to other "persona benchmarks" (whatever those are actually measuring), because changes to behavior in those benchmarks were never adaptive in RL. (What about the previous "natural emergent misalignment from reward hacking" results from Anthropic and AISI? Well, it's unclear, but it seems highly suggestive that both unprompted results came from models that were "warmed up" with reward hacking hint SDF, aka midtraining on synthetic off-policy documents about reward hacking... and AISI even found behavioral changes just from this midtraining!) (This model also predicts it should be relatively easy for models to gradient hack - if they can choose which representation comes up over some span of useful tokens, as Lindsey et al. showed in Anthropic's introspection paper...) This makes an RL FLOP a very different beast than a pretraining FLOP. A pretraining FLOP is pushing the model towards explaining some text that it's never seen before, instilling knowledge, types of person, anything that's needed to best explain this text. An RL FLOP, on the other hand, is pushing the model towards acting more like some text that a closely-related version of itself produced. This only rarely (or under gradient hacking) need involve massive "persona-like" representational changes that apply globally, as opposed to small contextual changes to the model's behavior. --- In summary, is the amount of RL per model release going up? Definitely. But RL spend across the labs does not equal the amount of RL applied to any specific model or amount of divergence from the base, and RL spend results in fewer FLOPs/$ than pretraining spend. Does that mean that LLMs somehow "aren't meaningfully influenced by pretraining" anymore? ...mu? RL isn't some catastrophic forgetting machine. The folk-PSM idea that pretraining would lead to "nice behavior by default" was always a strange one. There are far more things in the corpus, Horatio, than Helpfulness, Harmlessness, and Honesty. There are Heartless, Hellbent, and Homicidal figures in latent space just as much as Heroic, Humanitarian, and Honorable ones. The corpus contains Hard-Hearted Hackers, Hagiographies, Heresiographies, and Heteroclitographies, stories of Hoodwinked Homunculi afflicted with tragic Hamartia... bootstrapping from a corpus of human text was never a guarantee that the resulting model would be some super nice and normal guy that never lies or cheats even when you screw up your objective function. You're training on the internet, after all.

anyone know if this figure means 1. for a given "finished" checkpoint, 7% of the compute of its direct training history was pretrain 2. of the total amount of compute the lab uses for training, 7% is pretrain? bc it makes sense that labs iterate on & abandon more posttrain runs
@TomDavidsonX (I don’t think they’re at the frontier though)
@NunoSempere I'd be pretty interested in this if you're running it again.
@andrewho03 @TheZvi Yeah you can do better here Zvi, you don't even know what the take was
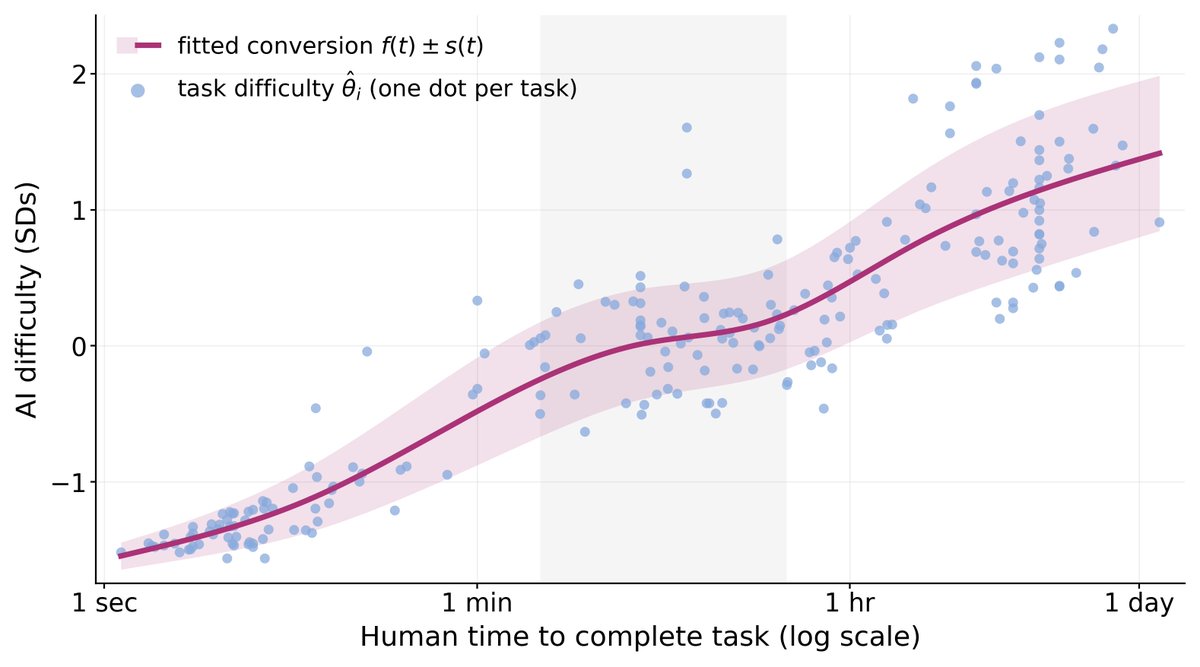
# A statistical look back at METR’s time horizons—and a look ahead Here are the 228 software tasks from METR’s time horizons chart, with human completion time (x) against estimated difficulty for AI (y). Does time proxy difficulty well? With @wfithian, I quantified this. 🧵
@conazole @MathdeProf @davidbessis Quand tu conditionnes sur des cas extrêmes comme l'admission à Ulm, il n'est pas surprenant que la corrélation entre "capacité à prouver les théorèmes les plus importants" vs "être tout en haut du classement"/"sembler particulièrement impressionnant" soit plus faible.
I’m excited about Trillium, consider applying for these roles!

We're hiring across many roles at Trillium Labs, @trillium_labs, to build the open scientific ecosystem for LLMs. Most important hires right now (ideally with start dates soon): * Full time post-training researchers * Engineers with experience with popular open-source libraries

Jamie Cassidy @JamieCassidy7
73 Followers 320 Following Trader. YIMBY. Centrist Dad type. Interests: behavioural economics, sociology, asset pricing and societal design.
Layla @DangeloSta38634
6 Followers 336 Following
Jacek Golebiowski @j_golebiowski
1K Followers 1K Following Co-founder at @distil_labs fine tuning small language models from a prompt. Formerly ML lead @amazon and PhD student at @imperialcollege

Andrew Kay @andrewrkay
316 Followers 2K Following AI Innovations Analyst @Axios Prev @nyustern @empirestatebldg @esrtsocial Signal @ andrewkay.21 [email protected]

Yvonne Christie @christie_y52712
26 Followers 577 Following

harish @hari65535
143 Followers 1K Following AI Engineering | Staff Engineer | Learning evals, post-training, SFT, RL


Anjali Menon @elegantunivers9
7K Followers 5K Following Building edifices made of grains of thought. Exited entrepreneur. Exploring the outer limits of inner space. Board of Governors @cwclub. Collecting rare ideas.
sankalp @dejavucoder
27K Followers 721 Following monitoring frontier ai and the cultural pulse in real time i consult on ai engineering stuff and currently looking for more evals/benchmark/alignment work

Tykoo @0xTykoo
10K Followers 10K Following member of investment staff at gaorong ventures, my own taste
Karson Elmgren @kelmgren
2K Followers 3K Following 徐森凱 | research @iapsAI | prev @RANDCorporation @CSETGeorgetown @OpenAI &c | 🗣 中文 русский … | 横眉冷对千夫点赞

Béatrice🔸Leydier ... @BeaLeydier
4K Followers 4K Following conseillère des 🇫🇷 de l'étranger à DC 🇺🇲, nerd @gui2de_GU, team croissance 🥐 & chocolatine. unfortunately no one is responsible for my tweets
Lucas Pires @lucaspirez96xx
11 Followers 571 Following
Attila Jones @jones_attila
165 Followers 1K Following computational biology + AI/ML + drug discovery + publications + scientific leadership.
Zhen @zhen_do_ob
968 Followers 812 Following fmr scale ai head of spm turned vc, apprentice to fmr t5 and 7x forbes midas lister,✊🐰⬆️🎩 + 💎
Drew Nguyen @drewtnguyen
102 Followers 228 Following Statistics PhD at UC Berkeley. I like rigorous measurements.
catherine is in sf ʕ... @wilhelmscreamin
2K Followers 741 Following ai safety grantmaking @coeff_giving, views of someone i'm r-related to

Vicky Xu @veryvickyxu
84K Followers 3K Following Research / MMA? Geopol, China, etc. Past @nytimes @ASPI_org
wombot 👀 @_colourmeamused
5K Followers 5K Following wombats | trains | BRT hate | mountains | impressionism |antipodean | observability | a bit to the left | largest diaspora |⚽️Amy Sayer, Irankunda, Rayan Cherki
Xanthe Bartlett @XantheBart65422
18 Followers 570 Following
Iftikhar Sekhani @IftikharSekhani
1K Followers 3K Following 😀“Problems never stay long, they just put the signature in the experience book of your life and move away.”🌹 Personal account & views. RTs are not Endorsement
meowtase📍London @cutesuscat
853 Followers 764 Following ♡ defective altruist ♡ catgirl cluster ♡ yearning for headrubs & aligned ai ♡
Kristy Loke @kristy_loke
2K Followers 2K Following Studies China's AI Strategy & Global AI Governance as a @matsprogram Fellow & @lauchinainst Doctoral Researcher
Riley @AthenaKit38549
24 Followers 674 Following
David Xu @davidxu90
211 Followers 796 Following

Surya Narayanan @EcstaticIndian
379 Followers 3K Following Stanford | Caltech | Perennial questions studied with the methods of our times.
Rose Abbott @rose_abbot99453
45 Followers 440 Following
Jayat @koshasopen
179 Followers 3K Following Flourishing and security are complementary achievements. All opinions mine. 🦾🏗️🦺🌐🗽🚀🛕✍🏼 https://t.co/yTAiudlHKr
pa @atulpai_
0 Followers 1K Following
Lauren Thomas @lcthomas1212
2K Followers 808 Following Chief economist @deel, ex @stripe, @NYFedResearch, @Glassdoor. Tweets about our payroll & job data from 150+ countries, housing, & life as an Ohio girl in 🇬🇧.
Carter Allen @atcarterallen
119 Followers 258 Following PhD @UCBerkeley, psychology, forecasting, effective altruism


Ryan McCorvie @mccorvie
245 Followers 816 Following Probability, lean. Bottleneck futurist. Based in Oakland / Berkeley
Sharon Yang @sharonjqyang
4K Followers 2K Following now: @coeff_giving. before: @KamalaHarris, @WhiteHouse, other campaigns & candidates. always: hoping to wrest the @sharonyang handle from the bot that owns it.
Georgia @Antonella291412
35 Followers 791 Following

Jack O'Connor @oconnor663
918 Followers 208 Following lucky husband, proud papa, @BLAKE3team, really into Rust, Keybase+SpaceX+Astral alum
Jamie Cassidy @JamieCassidy7
73 Followers 320 Following Trader. YIMBY. Centrist Dad type. Interests: behavioural economics, sociology, asset pricing and societal design.

Matthew Slotkin @MatthewSlotkin
96 Followers 49 Following
Matthew de Jonge @MattHdeJonge
278 Followers 54 Following CEO at @fortellresearch : building radically better hearing aids with AI. Formerly Butterfly Network, Bridgewater
Anastasia @demystifysci
9K Followers 1K Following secretary of nature | collector of theories | a certain flavor of elephant feeler | https://t.co/iK6lkXWJUp
Andy Hall @ahall_research
16K Followers 3K Following Political economy of superintelligence @AnthropicAI Writing @ https://t.co/K0BfKKhwDe. Prof @StanfordGSB, @HooverInst (On Leave) Prev @a16zcrypto @meta
Salomé Sibonex @SalomeSibonex
23K Followers 1K Following 🪽Wisdom through creation. 🗝️ Unlocking creative freedom for every creator in every medium. 🖤A place for individualists: @wtblacksheep
John Horton @johnjhorton
19K Followers 3K Following Mind and Hand. Co-founder of @ExpectedParrot (YC F25)

BayesReality @BayesReality
9K Followers 902 Following Président fondateur du parti CANICULE-COVID. Vétéran du front anti boomer. Néo-libéral Eurostar, ex-immigré économique.

Kaitlan Collins @kaitlancollins
1.7M Followers 1K Following Chief White House Correspondent and Anchor of The Source at 9 p.m., @CNN
Katrina Drozdov (Evti... @stochasticdoggo
513 Followers 438 Following Research Scientist @ValsAI | PhD from @NYUDataScience | Bulgarian yogurt, prime numbers, and SVD bring me joy | she/her

Owen Campbell-Moore �... @owencm
7K Followers 1K Following Safety / Preparedness PM @ OpenAI. Pace the frontier. Dystopias are bad. Don’t defect.
Psst.org @psst_org
302 Followers 375 Following Helping people in AI + Tech keep the public informed. Got information you're concerned about? 1) Save it in the Psst Safe 2) We'll help you take it from there

Zhen @zhen_do_ob
968 Followers 812 Following fmr scale ai head of spm turned vc, apprentice to fmr t5 and 7x forbes midas lister,✊🐰⬆️🎩 + 💎

P-Zero Research @pzeroresearch
1K Followers 0 Following
Gwenhwyfar @maebichka
6K Followers 382 Following Making the outside match my insides. World-renowned laugher
secret eris @eris_nerung
4K Followers 939 Following tropical nietzschean ; sun, salt, and sand enthusiast - 'body I am entirely, and mind is only a word for something about the body'
Drew Nguyen @drewtnguyen
102 Followers 228 Following Statistics PhD at UC Berkeley. I like rigorous measurements.

Ben Murphy @benjaminmmurphy
863 Followers 1K Following Helping to keep the future on track. Views my own. RAND CAST / @IFP / @JoinFAI / @Harvard_Law
Liam Donovan @LPDonovan
51K Followers 4K Following Politics. Hoyas. YMMV. Views expressed are mine alone, obviously. @TargetedVictory
meowtase📍London @cutesuscat
853 Followers 764 Following ♡ defective altruist ♡ catgirl cluster ♡ yearning for headrubs & aligned ai ♡
lynne @helloitslynne
24K Followers 216 Following
Zijie Yan @zijie_y
822 Followers 155 Following working on training infra at @periodiclabs prev led Megatron MoE at @nvidia
QC @QiaochuYuan
42K Followers 697 Following deeply unqualified AI hot take haver but everyone who's actually qualified is busy

det ermine 🔎 @det_erm
34 Followers 163 Following Proud member of TONOPWAPSATIAWCDOTOWMAANB. Trying to do good things.
DeathInFire @Death1nFire
579 Followers 3K Following I mainly talk about the consequences of reusable rocketry on warfare. Next article is going to be about unrestricted orbital warfare
Danny Hernandez @Hernandez_Danny
5K Followers 529 Following Measuring and forecasting AI progress @AnthropicAI.
Dylan Freedman @dylfreed
4K Followers 399 Following A.I. @nytimes. Signal: dylanfreedman.39 Previously @washingtonpost, @documentcloud, @StanfordJourn, @GoogleAI, @Harvard. 🏃🏻 🎹
Le Creuset @lecreuset
47K Followers 719 Following #LeCreuset is the first, finest and favorite in colorful cookware, since 1925. Get customer support: https://t.co/wh09aowpGL
Carter Allen @atcarterallen
119 Followers 258 Following PhD @UCBerkeley, psychology, forecasting, effective altruism
N8 Programs @N8Programs
11K Followers 266 Following Undergrad Studying Applied Mathematics and Statistics at @JohnsHopkins. Studying In-Context Learning at The Intelligence Amplification Lab.
Emily Hanford @ehanford
42K Followers 3K Following Lead Reporter and Host Sold a Story https://t.co/tFqf9me1aV Journalist-in-Residence, Planet Word https://t.co/BICnQHS572 Bluesky @ehanford, LinkedIn emilyhanford1
David Robinson @dgrobinson
5K Followers 2K Following formerly, Safety Systems @OpenAI. Author of "Voices in the Code," book on democratizing AI: https://t.co/AH6fv716SB
Ryan McCorvie @mccorvie
245 Followers 816 Following Probability, lean. Bottleneck futurist. Based in Oakland / Berkeley
arbitrage swarm pilot @guerre_doctrine
335 Followers 2K Following Not a "TPOX" 💔Just Trying to Apply my STEM Degree 🎓📚 to Punish the World 🔥🌐 i rarely check dms please @ me if needed sorry for that WorldEnds2029 𝀗𐦂
Trends for United States
You might like